
Tag: LLM chunking
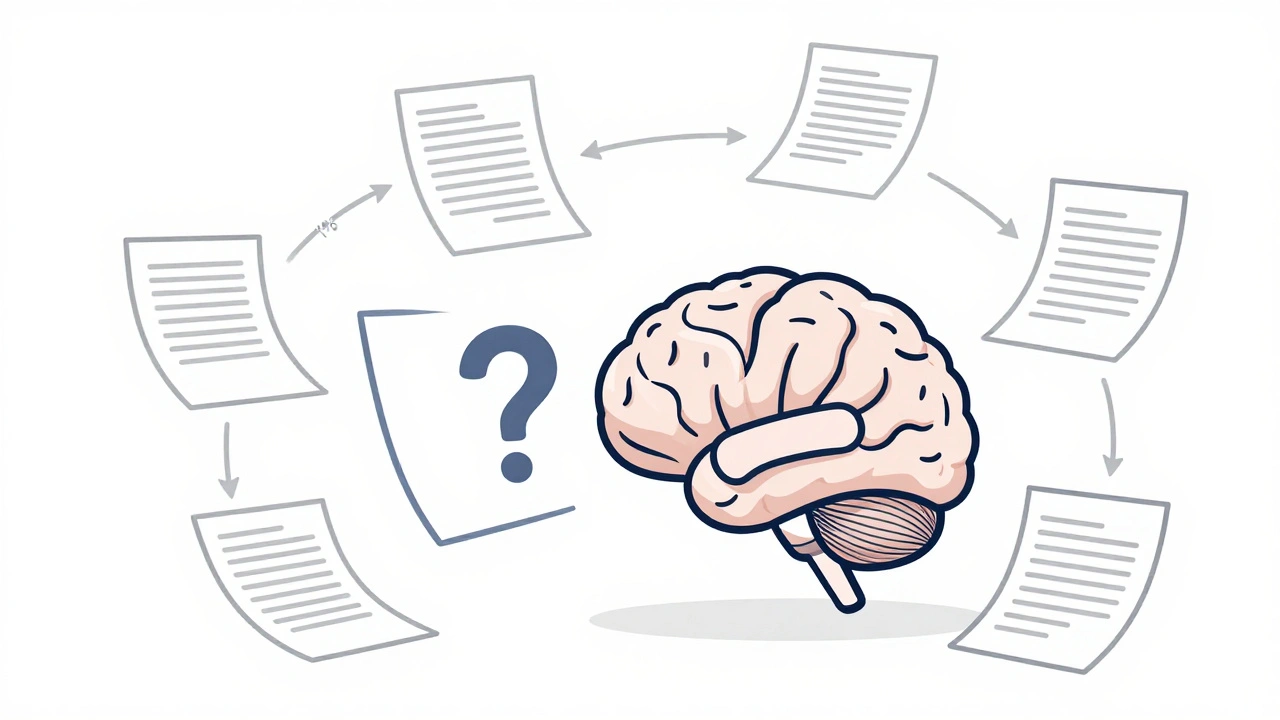
Chunking strategies determine how well RAG systems retrieve information from documents. Page-level chunking with 15% overlap delivers the best balance of accuracy and speed for most use cases, but hybrid and adaptive methods are rising fast.
Categories
 Artificial Intelligence
Archives
Recent-posts
Confidential Computing for LLM Inference: Securing Data and Models with TEEs
Oct, 28 2026
Documentation First: Why AI Output Is Just a Draft
Sep, 18 2026

Why Multimodality Is the Future of Generative AI Beyond Text-Only Systems
Nov, 15 2025

Allocating LLM Costs Across Teams: Chargeback Models That Actually Work
Jul, 26 2025

Localization and Translation Using Large Language Models: How Context-Aware Outputs Are Changing the Game
Nov, 19 2025