You ask an Large Language Model (LLM) for a medical dosage or a legal precedent, and it answers with absolute confidence. The problem? It might be completely wrong. This is the hallucination problem, where models generate plausible but factually incorrect information. Recent benchmarks like HaluEval show that even top-tier models like GPT-4 produce factual errors in 15-25% of responses. That’s not just a glitch; it’s a barrier to using AI in high-stakes fields like healthcare and finance.
So, how do we fix this without slowing everything down to a crawl? You can’t just wait until the text is finished to check it. You need online verification strategies-systems that check facts as they are being generated or immediately after claim extraction. This isn't about perfecting every sentence; it's about building a safety net that catches the big lies before they reach the user. Let’s look at how these systems work, what tools are actually good, and where they still fail.
The Three-Stage Pipeline of Factuality Verification
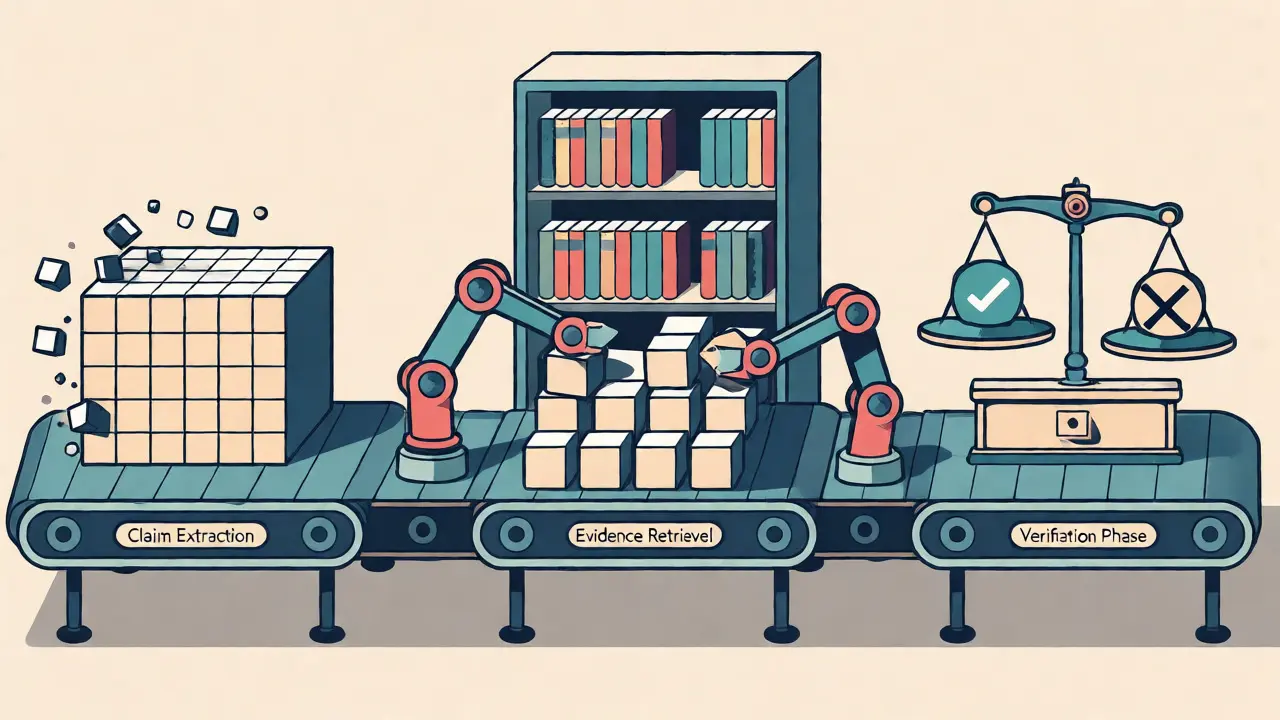
Most modern verification frameworks don’t just “check” the whole paragraph at once. They break it down. Think of it like a factory assembly line with three distinct stations. If you skip one, the product fails.
First, there’s Claim Extraction. This phase decomposes the generated text into atomic, context-independent claims. For example, "The Eiffel Tower is in Paris and was built in 1889" becomes two separate claims: "The Eiffel Tower is in Paris" and "The Eiffel Tower was built in 1889." State-of-the-art systems like FactScore achieve 87.3% precision here. Why does this matter? Because verifying a complex sentence is harder than verifying simple truths.
Next comes Evidence Retrieval. The system searches authoritative sources-Wikipedia, verified news databases, or your company’s internal knowledge base-to find proof for each claim. Tools like FacTool use a mix of BM25 (keyword matching) and dense retrieval (semantic understanding) to hit 92.7% evidence recall on standard benchmarks. If the system can’t find evidence, it flags the claim as unverifiable rather than false.
Finally, the Verification Phase kicks in. Here, a verifier decides if the evidence supports, contradicts, or is irrelevant to the claim. This can be done via rule-based logic, Natural Language Inference (NLI) models, or by asking another LLM to judge the match. GPT-4-based verifiers hit 78.4% accuracy on FactBench, but they’re expensive and slow.
Comparing Major Frameworks: Speed vs. Accuracy
Not all verification tools are created equal. Some are built for research labs where accuracy is king; others are built for production servers where speed pays the bills. Here’s how the big players stack up against each other.
| Framework | Avg. Accuracy | Latency per Claim | Cost Efficiency | Best Use Case |
|---|---|---|---|---|
| OpenFactCheck | 81.7% | High (47 min/doc) | Moderate | R&D, Custom Pipelines |
| FactScore | 76.8% | Low (2.3 sec) | High | Production, High Volume |
| Noblis G3 | 85.2% | Variable | Low (High Setup) | Enterprise/Gov Docs |
| Perplexity.ai System | 72.1% | Very Low (1.8 sec) | High | User-Facing Search |
OpenFactCheck, released by Stanford researchers in March 2024, is the current gold standard for flexibility. It integrates multiple modules (CustChecker, LLMEval, CheckerEval) and supports 14 different claim processors. But it’s heavy. Running a full evaluation takes nearly an hour per document on standard hardware. It’s great for debugging why your model failed, but terrible for real-time chat apps.
In contrast, FactScore prioritizes efficiency. It’s 3.2x faster than OpenFactCheck but sacrifices some accuracy (76.8% vs 81.7%). Developers love it because it works out of the box, but customizing it for niche domains like medicine requires serious NLP expertise. As one Reddit user noted, adapting it for medical data feels like needing a PhD in linguistics.
Then there’s the commercial option: Perplexity.ai’s internal verification. It’s fast (1.8 seconds latency) but lacks transparency. You get a result, but you don’t always know *why* the system flagged something. For many businesses, that opacity is a dealbreaker when compliance matters.
The Hidden Costs: Latency, Money, and False Positives
Here’s the uncomfortable truth: verification costs money and time. If you use a powerful verifier like Factcheck-GPT, you’re looking at $0.042 per claim and 12.7 seconds of delay. Imagine checking 10 claims in a response-that’s over two minutes of waiting and $0.42 per query. For a startup burning cash, that’s unsustainable.
Llama-3-8B based verifiers offer a better balance, hitting 72.1% accuracy for just $0.008 per verification. But cheaper often means more noise. False positives-where the system flags a true statement as false-average around 18.7% across implementations. Users hate seeing "Unverified" next to basic facts like "Water boils at 100°C." To mitigate this, engineers implement confidence thresholds. If the verifier’s confidence score is below a certain level, the system ignores the flag. This simple trick reduces false positives by 34.1%, according to GitHub issue resolutions.
Another major pitfall is temporal knowledge. Systems struggle with time-sensitive claims. On the FACTOR benchmark, accuracy drops by 32.6% for claims involving dates or recent events. If your LLM says "The CEO of Apple is Tim Cook," that’s fine. But if it says "The stock price closed at $X yesterday," the verifier needs access to real-time financial data, which most static knowledge bases lack.
Where Current Systems Still Fail
Despite the hype, automated fact-checking isn’t magic. Experts remain skeptical. Percy Liang from Stanford pointed out at ACL 2024 that these systems miss 23.7% of subtle factual errors that human fact-checkers catch. He argues they provide "scaffolding," not replacement.
Cultural bias is another blind spot. HaluEval’s cross-cultural analysis shows a 41.3% drop in accuracy for non-Western topics. If you’re deploying an LLM for global users, verify that your knowledge base covers local history, laws, and cultural norms. A system trained primarily on English Wikipedia might confidently misstate facts about Japanese business etiquette or African geography.
Counterfactual reasoning is perhaps the hardest hurdle. Questions like "What would have happened if Lincoln hadn't been assassinated?" require logical deduction beyond simple fact retrieval. Across all platforms, accuracy on counterfactual tasks drops below 45%. Don’t rely on automated verification for creative or hypothetical scenarios.
Practical Implementation: Getting Started Without Losing Your Mind
If you’re ready to implement this, don’t try to boil the ocean. Start small. The OpenFactCheck documentation suggests a 15-20 hour onboarding process for experienced ML engineers. Break it down:
- Setup (4-6 hours): Get the environment running. Expect installation headaches; 63% of users report difficulties configuring custom knowledge bases.
- Customization (8-10 hours): Tune the claim extractor for your domain. Generic extractors fail on technical jargon.
- Integration (3-4 hours): Connect it to your API pipeline.
Pro tip: Use hybrid retrieval. Combining keyword search (BM25) with semantic search (dense vectors) reduces false negatives by 27.3%. Also, pre-filter your content. Not every sentence needs verification. Skip greetings, opinions, and obvious statements. Only verify high-risk factual claims. This cuts the verification load significantly.
Be prepared for a learning curve. Stack Overflow surveys indicate a 6-8 week ramp-up time to achieve production-ready implementations. You’ll need skills in vector database management and intermediate NLP concepts. Documentation quality varies wildly-OpenFactCheck scores high on comprehensiveness but low on practical examples, so expect to read source code.
The Future: Self-Correction and Real-Time Checks
The industry is shifting from post-hoc checking to real-time verification. Instead of generating a whole paragraph and then checking it, newer models pause mid-generation to verify high-risk claims. This "self-verification" approach reduces final output errors by an additional 22.4%, according to MIT studies.
OpenFactCheck 2.0, released in January 2025, introduced optimized algorithms that cut latency by 3.8x. Meanwhile, the LLM-Oasis framework highlights persistent gaps, showing that even GPT-4o achieves only 60% accuracy on complex verification tasks. The goal isn’t perfection; it’s reliability.
Gartner predicts that 95% of enterprise LLM deployments will include some form of factuality verification by 2027. Regulatory pressure, especially from the EU’s AI Act, is forcing companies to prove their AI doesn’t lie. If you’re building LLM applications today, ignoring factuality is no longer an option-it’s a liability.
Why can't I just use one LLM to check another LLM?
While possible, it's inefficient and prone to shared biases. If both models were trained on similar flawed data, they might agree on a falsehood. Dedicated verification frameworks use external knowledge bases (like Wikipedia or proprietary docs) to provide ground-truth evidence, breaking the echo chamber.
How much does online verification increase latency?
It depends on the tool. Lightweight systems like FactScore add about 2.3 seconds per claim. Heavyweight systems like Factcheck-GPT can add 12+ seconds. For real-time chat, you typically limit verification to critical claims or use asynchronous background checks to keep the UI responsive.
Are open-source tools like FactScore free to use?
Yes, the software itself is open-source. However, you pay for compute resources (GPU/CPU time) and potentially API costs if you use cloud-based LLMs for the verification step. Self-hosting avoids API fees but requires infrastructure maintenance.
Can verification handle subjective or opinion-based statements?
Generally, no. These systems are designed for objective facts (e.g., "Paris is in France"). Subjective claims (e.g., "This movie is boring") lack a single verifiable truth. Most pipelines filter out opinions before verification to avoid false flags.
What is the biggest challenge in implementing these systems?
Configuring the knowledge base. 63% of users cite difficulty in setting up custom evidence retrievers. Ensuring your knowledge base is up-to-date, comprehensive, and structured correctly for retrieval is often harder than coding the verification logic itself.
 Artificial Intelligence