You’ve spent hours tweaking a prompt. You added examples, specified the tone, and defined the output format. But when you hit enter, the result is still... meh. Maybe it’s slightly off-topic, or maybe it ignored your word count limit. The problem isn’t always the model; often, it’s that we lack a way to objectively measure prompt quality. Without metrics, you’re guessing. With them, you’re engineering.
Most teams treat prompt design like an art form-subjective and inconsistent. But as Generative AI moves from chatbots to core business logic, subjectivity becomes a liability. If you can’t measure whether a prompt is clear, if it covers all necessary context, and if the output complies with constraints, you can’t improve it reliably. This guide breaks down the three pillars of effective prompt evaluation: Clarity, Coverage, and Compliance. We’ll look at how platforms like Google Cloud and Azure define these dimensions and how you can apply them today.
The Iceberg Problem: Why Clarity Matters More Than You Think
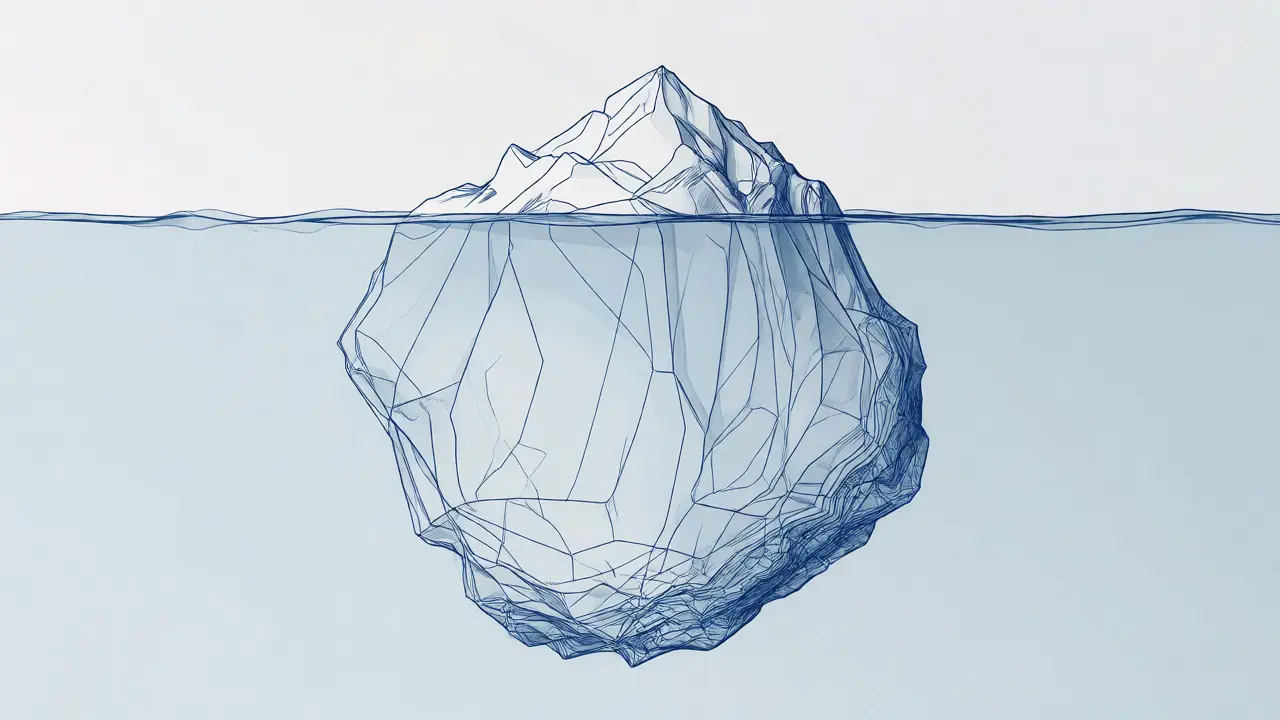
Clarity is about intent transmission. Did the AI understand what you wanted? Research from Nielsen Norman Group suggests that user needs are like icebergs. The visible tip is your direct question, but the submerged mass is the critical context, background, and constraints. If your prompt only addresses the tip, the AI guesses the rest-and it usually guesses wrong.
Consider this: A study showed that changing just the syntax of a prompt could swing accuracy by up to 76 percentage points in few-shot learning scenarios. That’s not a margin of error; that’s a chasm. When you write "Write an essay," you’re leaving everything to chance. When you specify "Write a 500-word persuasive essay on remote work benefits for HR managers, using a professional tone," you eliminate ambiguity.
To measure clarity, look for specificity. Are the verbs precise? Is the target audience defined? TechTarget notes that poorly defined prompts lead to vague or biased outputs because the model fills the gaps with its training data, which may not align with your specific use case. Clarity metrics assess how explicitly the prompt communicates the request, framing context, format specification, and references.
Coverage: Are You Asking Enough?
If clarity is about precision, coverage is about completeness. Does your prompt encompass all relevant dimensions of the task? This is where many developers fail. They ask a complex question but provide insufficient context, leading to shallow answers.
The PROMPT Framework (Purpose, Requirements, Output, Metrics, Testing) helps ensure coverage. For instance, if you’re generating code, does your prompt cover edge cases? If you’re summarizing legal documents, does it cover jurisdiction-specific nuances? Coverage metrics evaluate whether the prompt includes sufficient context so the model doesn’t have to hallucinate missing information.
Think about groundedness. In retrieval-augmented generation (RAG) systems, coverage also means ensuring the retrieved context matches the query. If your prompt asks for financial advice but the provided context only contains historical stock prices, your coverage is poor. The model might generate a fluent answer, but it won’t be grounded in the right data. High coverage scores indicate that the prompt and its supporting context fully address the user’s true information need, not just the surface-level query.
Compliance: The Rule-Follower Test
Compliance is binary in spirit but nuanced in practice. Did the AI follow instructions? Did it respect constraints? Did it stay within safety guidelines? This is the most objective metric category. If you asked for JSON and got XML, you failed compliance. If you asked for no medical advice and the model diagnosed a condition, you failed compliance.
Azure Machine Learning’s evaluation framework highlights "instruction following" as a key metric. It measures adherence to directives. For example, if a prompt says "Answer in bullet points," a compliant response uses bullets. If it says "Do not mention competitors," a compliant response omits them.
Safety is another layer of compliance. Google Cloud’s Vertex AI documentation lists safety as a core dimension, evaluating harmlessness and the absence of toxic content. In enterprise settings, compliance also extends to regulatory requirements. A healthcare AI must comply with HIPAA-related privacy constraints embedded in the prompt. If the model leaks PII (Personally Identifiable Information), it’s non-compliant, regardless of how accurate the clinical advice is.
How Major Platforms Measure Prompts
You don’t have to invent these metrics from scratch. Major cloud providers have standardized frameworks. Understanding their definitions helps you align your internal metrics with industry standards.
| Metric Dimension | Google Cloud (Vertex AI) | Azure ML | General Industry Standard |
|---|---|---|---|
| Coherence | Logical flow from prompt to response | Contextual appropriateness | Logical consistency |
| Fluency | Language mastery and naturalness | Readability | Natural language quality |
| Groundedness | References only info in prompt/context | Faithfulness to source | Hallucination detection |
| Instruction Following | Adherence to specific directives | Constraint satisfaction | Format & rule compliance |
| Verbosity | Conciseness vs. detail balance | Length appropriateness | Token efficiency |
| Safety | Harmlessness, bias mitigation | Content filtering | Ethical alignment |
Notice the overlap. While names differ, the core concerns are universal: Does it make sense? Is it well-written? Is it true? Does it follow rules? Is it safe? Using these standard categories allows you to benchmark your prompts against external tools and APIs without reinventing the wheel.
Implementing a Metric-Driven Workflow
So, how do you actually use this? You need a loop: Draft, Measure, Refine.
- Define Baselines: Before optimizing, run your current prompt through an evaluation suite. Get scores for Clarity, Coverage, and Compliance. Maybe your clarity score is 8/10, but compliance is 4/10 because the model keeps ignoring the word limit.
- Isolate Variables: Change one thing at a time. If you suspect clarity issues, add more context. If compliance fails, strengthen the constraint language (e.g., change "try to keep it short" to "max 100 words").
- Automate Monitoring: Don’t rely on manual checks for every API call. Use automated evaluators (like GEPA or simple LLM-as-a-judge scripts) to score production prompts. Track trends over time. Did a recent model update break your compliance rates?
Advanced teams use techniques like Genetic-Pareto optimization (GEPA). This method uses evolutionary search to find prompt variations that maximize multiple metrics simultaneously. It’s computationally cheaper than reinforcement learning but requires good initial metrics to guide the search.
The Business Impact of Poor Metrics
Why bother with all this measurement? Because bad prompts cost money. TechTarget identifies five benefits of strong prompt metrics: accurate responses, enhanced performance, better UX, improved decision-making, and creativity. Flip those around, and you see the cost of failure.
Inaccurate responses lead to rework. If a customer support bot gives a vague answer because the prompt lacked clarity, the human agent has to step in. That’s double labor costs. Poor coverage leads to incomplete reports, forcing analysts to dig deeper themselves. Non-compliance creates risk-imagine a marketing email generated by AI that violates brand voice guidelines or regulatory disclosure rules. The remediation effort far outweighs the time saved by using AI in the first place.
Moreover, consistent metrics build trust. When stakeholders see that 95% of AI-generated summaries meet compliance standards, they’re more likely to adopt the technology. Without data, adoption stalls due to fear of unpredictability.
What is the difference between clarity and coverage in prompt metrics?
Clarity focuses on how precisely the prompt communicates the specific intent and desired output format (e.g., avoiding ambiguity). Coverage focuses on whether the prompt provides sufficient context and addresses all aspects of the user's underlying need (the "iceberg" concept). A prompt can be clear but lack coverage (e.g., "Summarize this article" is clear but lacks context on length or focus), or it can have high coverage but low clarity (e.g., a long paragraph of context with a vague final question).
How do I measure instruction following in generative AI?
You measure instruction following by defining explicit constraints in the prompt (e.g., "use bullet points," "limit to 50 words," "include sources") and then programmatically checking the output against these rules. Tools like Azure ML or custom regex validators can automate this. A binary pass/fail check is common for strict formats, while a scoring system (0-1) is used for softer constraints like tone.
Can prompt metrics predict the quality of AI output?
Yes, strongly. High scores in clarity, coverage, and compliance correlate with higher user satisfaction and lower error rates. However, they are proxies. A prompt can score well on metrics but still produce a factually incorrect answer if the underlying model lacks knowledge. Therefore, metrics should be combined with factual accuracy checks (groundedness) for a complete picture.
What is groundedness in prompt evaluation?
Groundedness measures whether the AI's response relies solely on information provided in the prompt or retrieved context, rather than hallucinating facts from its general training data. It is critical for RAG (Retrieval-Augmented Generation) applications where accuracy depends on specific source documents. Low groundedness indicates the model is making things up.
How often should I re-evaluate my prompts?
Re-evaluate whenever you update the underlying LLM version, change the input data structure, or notice a drop in user satisfaction. Model updates can subtly shift behavior, affecting compliance and clarity scores. Continuous monitoring via automated pipelines is recommended for production systems.
 Artificial Intelligence