
Tag: cost per token
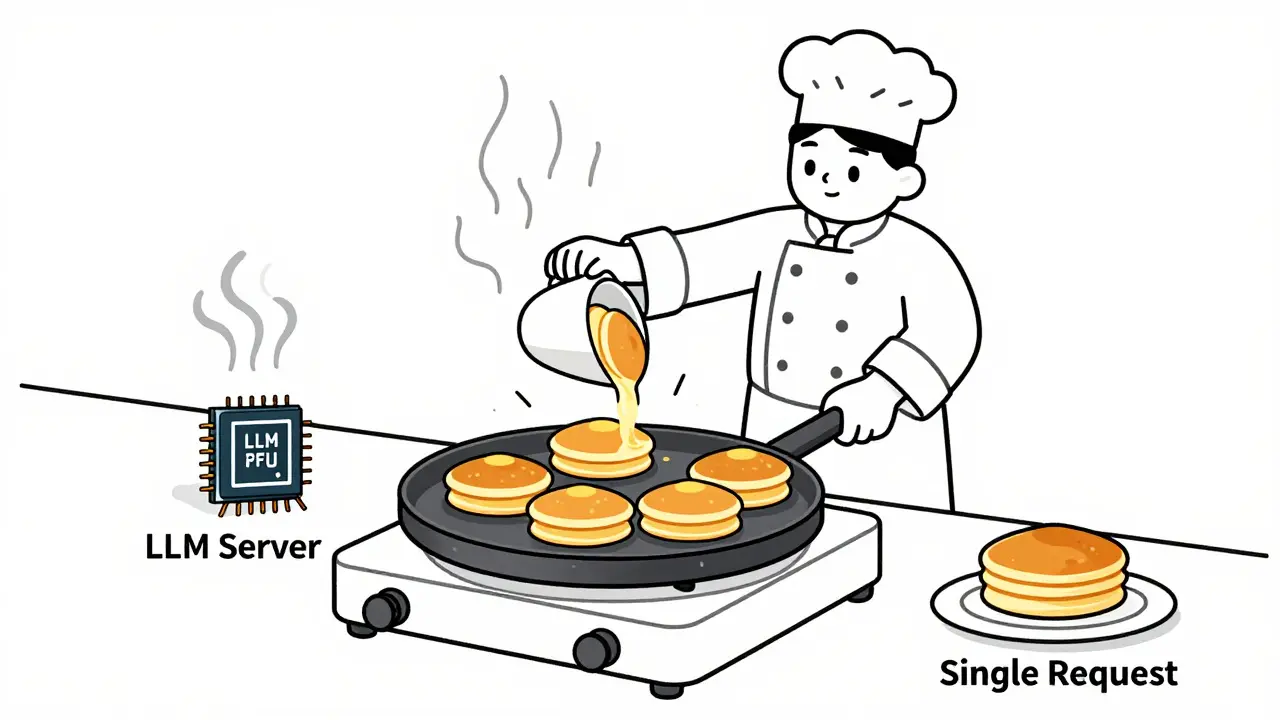
Learn how to choose optimal batch sizes for LLM serving to cut cost per token by up to 87%. Discover real-world results, batching types, hardware trade-offs, and proven techniques to reduce AI infrastructure costs.
Categories
 Artificial Intelligence
Archives
Recent-posts
vLLM vs TGI: Which LLM Serving Framework Should You Use in 2026?
Apr, 5 2026
Contact Center Analytics with Large Language Models: Sentiment and Intent Detection
Mar, 14 2026
Vibe Coding Adoption Metrics and Industry Statistics That Matter
Mar, 29 2026
Ethical AI Agents for Code: Guardrails that Enforce Policy by Default
Jun, 3 2026

Key Components of Large Language Models: Embeddings, Attention, and Feedforward Networks Explained
Sep, 1 2025