
Tag: LLM deployment
Deciding between API-based LLMs and on-prem deployment? We break down latency, control, and hidden costs to help you choose the right architecture for your AI projects.
Only 14% of enterprises successfully scale Generative AI from PoC to production. Learn how to avoid the 'valley of death' by focusing on security, cost management, and clear ROI metrics.
Struggling with LLM costs or performance? Learn when to compress models via quantization versus switching to smaller architectures. Make smarter AI deployment decisions.
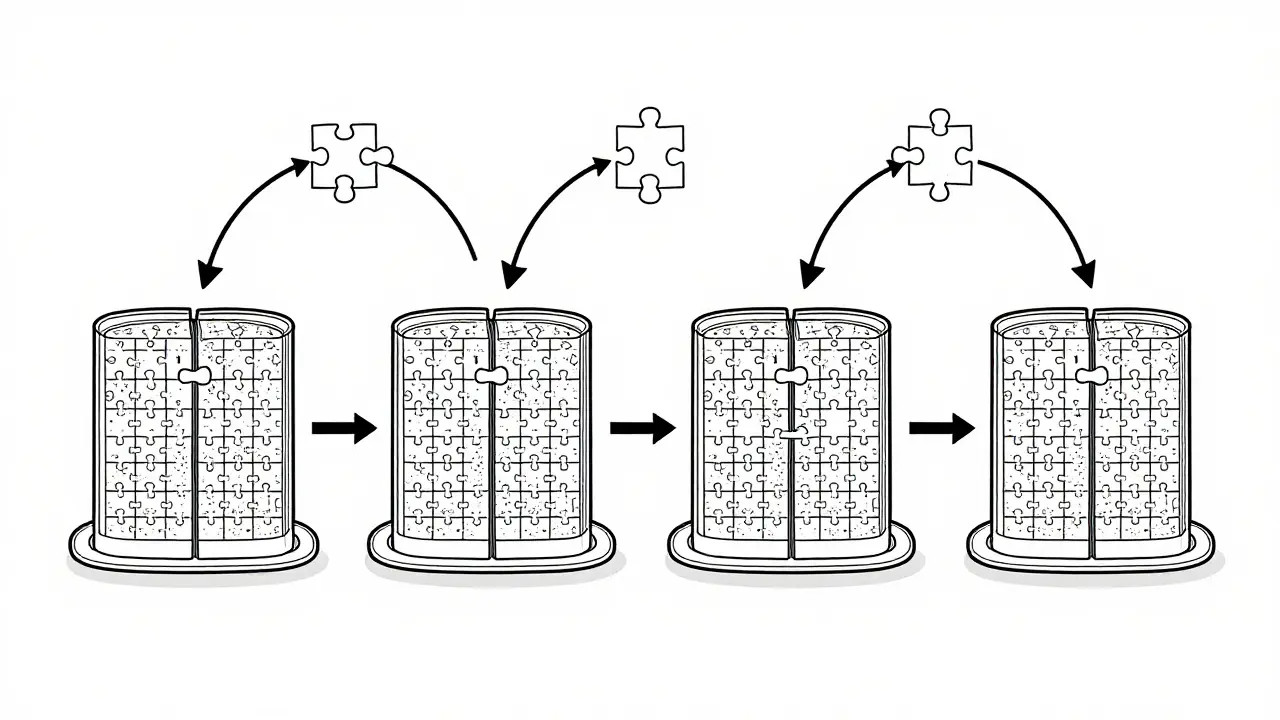
Tensor parallelism lets you run massive LLMs across multiple GPUs by splitting model layers. Learn how it works, why NVLink matters, which frameworks support it, and how to avoid common pitfalls in deployment.
Categories
 Artificial Intelligence
Archives
Recent-posts
Cross-Lingual Transfer in LLMs: How AI Learns New Languages Without Retraining
Aug, 3 2026
Workflow Automation with LLM Agents: When Rules Meet Reasoning
Jun, 28 2026
Continual Learning in Generative AI: How to Adapt Models Without Catastrophic Forgetting
Jul, 3 2026
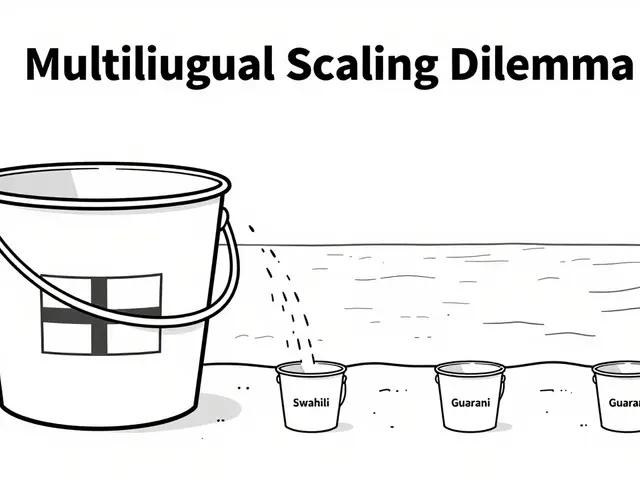
Scaling Multilingual LLMs: The Data Balance and Coverage Guide
Jun, 21 2026
How Finance Teams Use Generative AI for Smarter Forecasting and Variance Analysis
Dec, 18 2025