
Tag: token efficiency
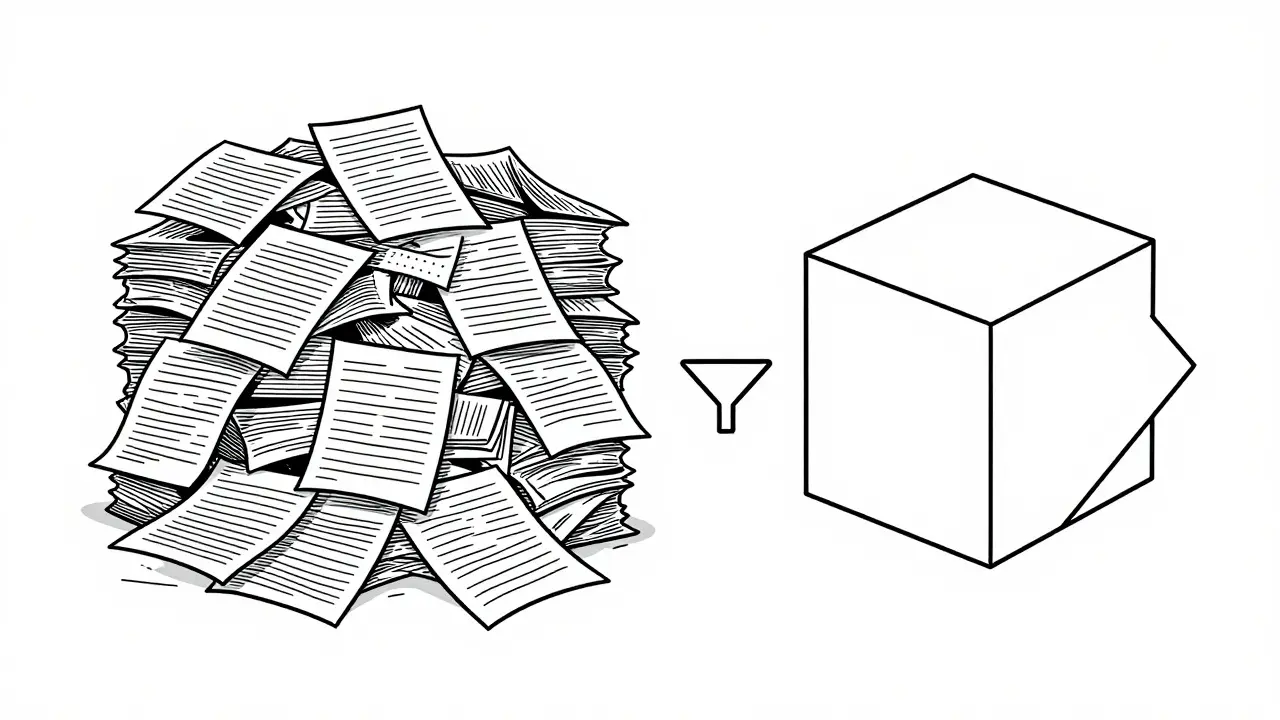
Learn how compression-aware prompting optimizes small LLMs by distilling prompts. Explore techniques like TPC and LJMLingua to cut costs, boost speed, and improve RAG accuracy.
Categories
 Artificial Intelligence
Archives
Recent-posts
Governance Models for Generative AI: Councils, Policies, and Accountability
Nov, 10 2026
Pretraining Objectives in Generative AI: Masked Modeling, Next-Token Prediction, and Denoising
Mar, 8 2026
Token Probability Calibration in Large Language Models: How to Fix Overconfidence in AI Responses
Jan, 16 2026
Why Understanding Every Line of AI-Generated Code Isn't the Goal in Vibe Coding
Mar, 27 2026
Secure Embedding Stores: How to Protect Vectorized Private Documents in 2026
Jul, 4 2026