
Tag: transformer architecture
Explore how attention mechanisms evolved from simple alignment weights to Flash Attention. Learn why self-attention powers modern LLMs and how IO-aware optimizations solve memory bottlenecks.
Discover how Long Short-Term Memory (LSTM) networks solved early NLP challenges, paving the way for Transformer-based Large Language Models. Learn why parallel processing and attention mechanisms revolutionized AI.

Discover how Multi-Head Attention enables LLMs to analyze language from parallel perspectives. Learn its mechanics, benefits, and future trends.
Discover how autoregressive text generation powers modern LLMs. Learn about next-token prediction, causal modeling, and decoding strategies like temperature and top-p.
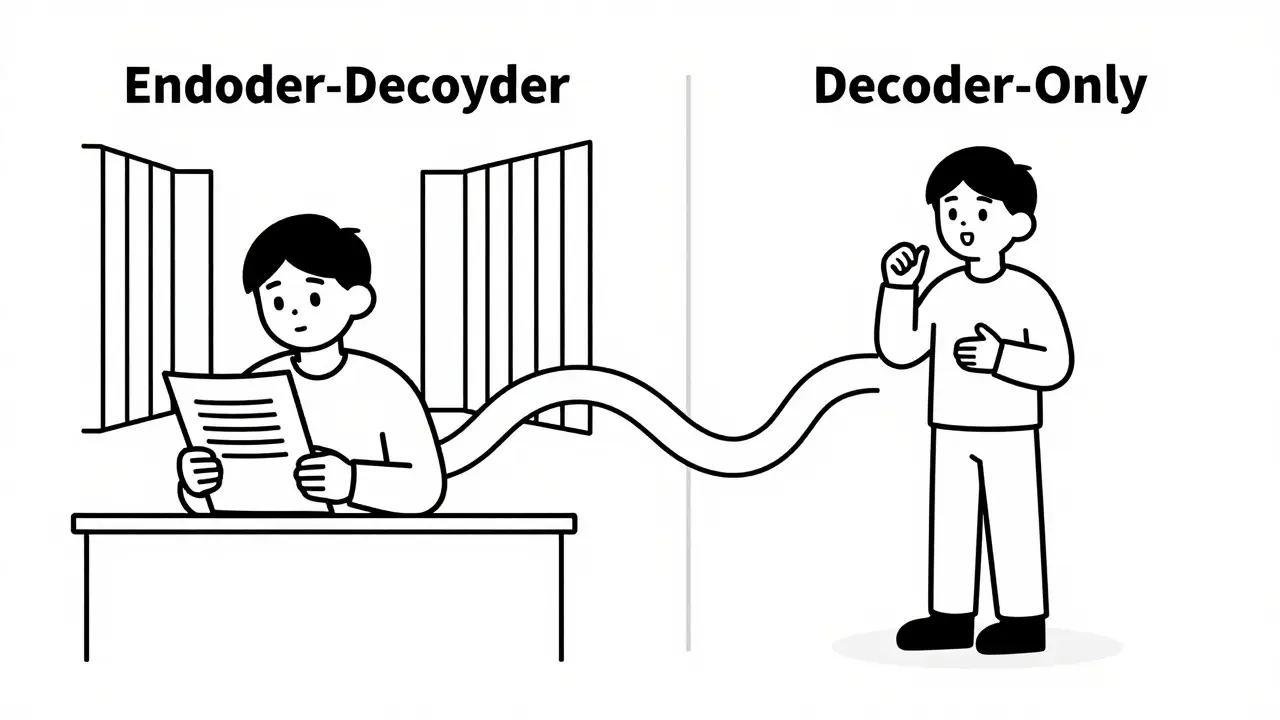
Explore the key differences between encoder-decoder and decoder-only transformer architectures. Learn which LLM design fits your project based on speed, accuracy, and task type.
Explore the technical details of Transformer architecture, the backbone of modern LLMs. Learn how self-attention, MLP layers, and residual connections enable AI to understand and generate human language.
Discover how positional encoding solves the order-blindness of Transformers. Learn about sinusoidal, learned, and RoPE methods that enable LLMs to understand context and sequence.
Discover how Large Language Models master language through self-supervised learning and attention mechanisms. Explore the technical foundations of syntax and semantic capture.
Learn how embeddings, attention, and feedforward networks form the core of modern large language models like GPT and Llama. No jargon, just clear explanations of how AI understands and generates human language.
Categories
 Artificial Intelligence
Archives
Recent-posts
Citation and Attribution in RAG Outputs: How to Build Trustworthy LLM Responses
Jul, 10 2025
Compression Impact on Multilingual and Domain-Specific Large Language Models
Jul, 23 2026
Vibe Coding Dependency Management: How to Upgrade Without Breaking Your App
May, 5 2026
Generative AI Cost Models 2026: Build vs Buy, Token Pricing & Infrastructure
Jul, 7 2026
Curriculum and Data Mixtures: Accelerating LLM Scaling in 2026
May, 31 2026