
Tag: vLLM deployment
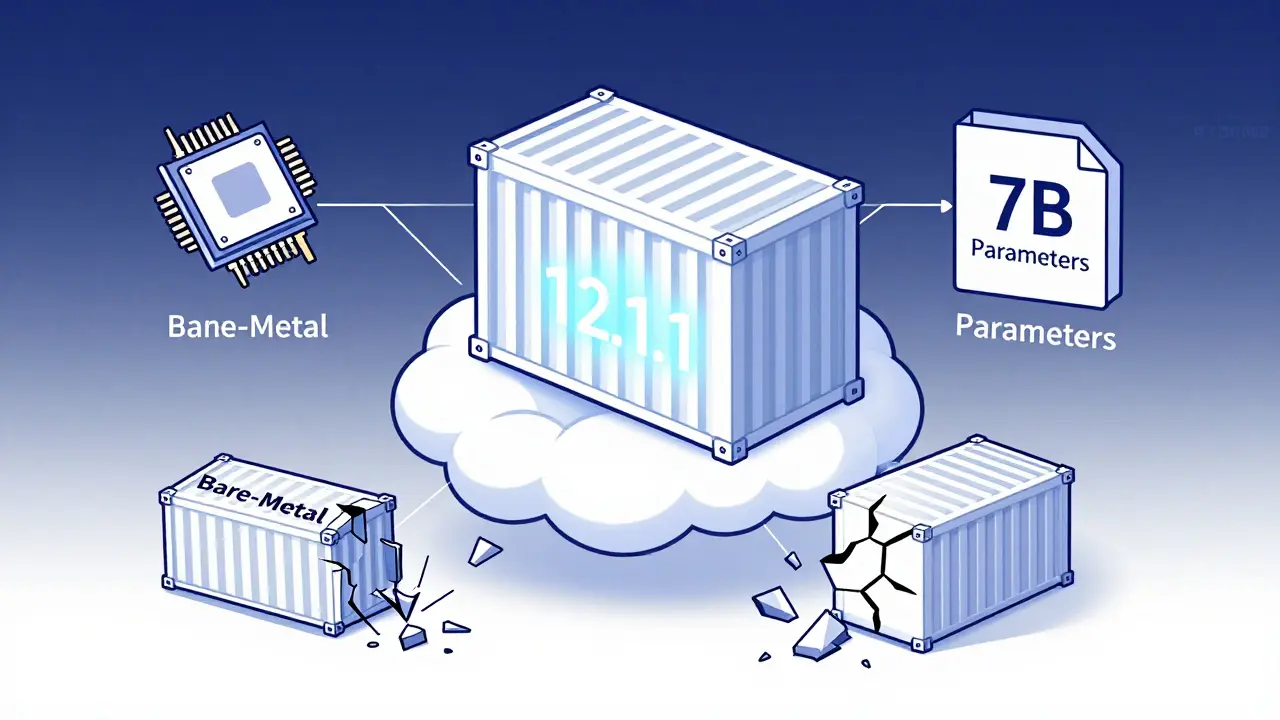
Containerizing large language models requires precise CUDA version matching, optimized Docker images, and secure model formats like .safetensors. Learn how to reduce startup time, shrink image size, and avoid the most common deployment failures.
Categories
 Artificial Intelligence
Archives
Recent-posts
Vibe Coding for Full-Stack Apps: What to Expect from AI Implementations
Feb, 21 2026
Security for RAG: Protecting Private Documents in LLM Workflows
Oct, 7 2026
Velocity vs Risk: Balancing Speed and Safety in Vibe Coding Rollouts
Oct, 15 2025
Adapter Layers and LoRA: Efficient LLM Customization Guide
Aug, 31 2026
Calibration and Outlier Handling in Quantized LLMs: How to Keep Accuracy When Compressing Models
Jul, 6 2025