
Tag: CUDA for LLMs
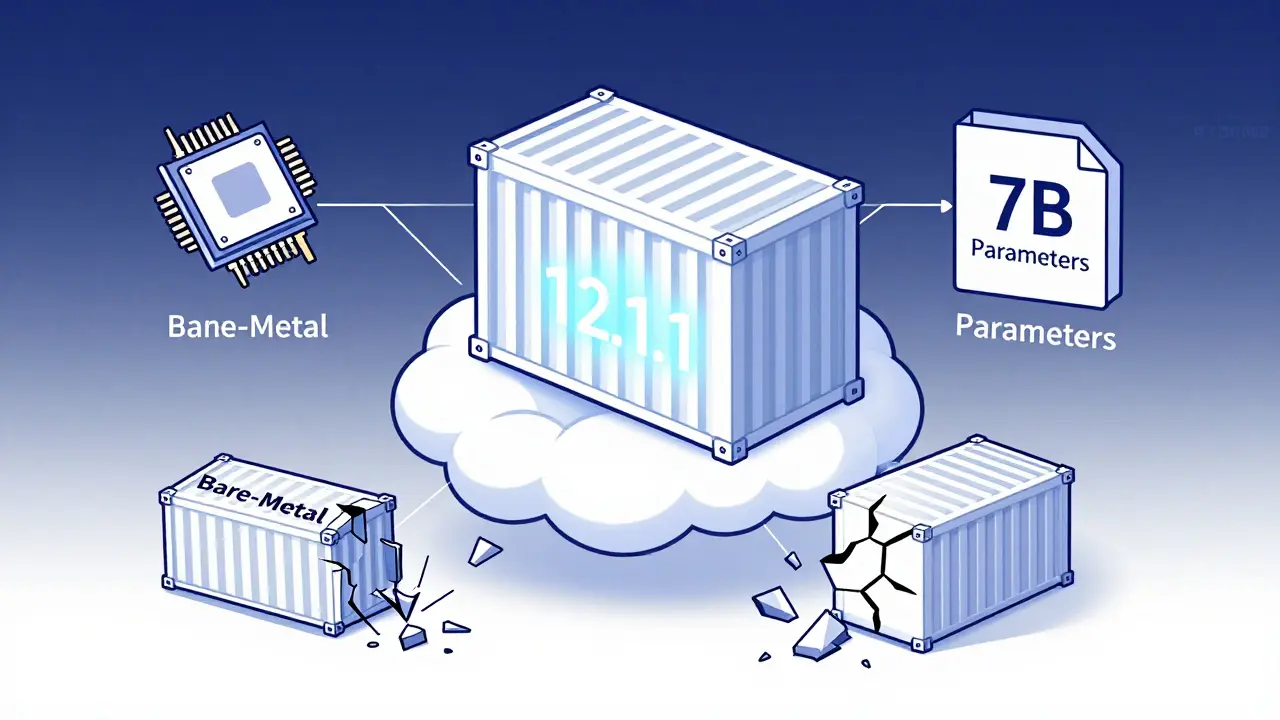
Containerizing large language models requires precise CUDA version matching, optimized Docker images, and secure model formats like .safetensors. Learn how to reduce startup time, shrink image size, and avoid the most common deployment failures.
Categories
 Artificial Intelligence
Archives
Recent-posts
Secure Embedding Stores: How to Protect Vectorized Private Documents in 2026
Jul, 4 2026
How Training Duration and Token Counts Affect LLM Generalization
Dec, 17 2025
Speculative Decoding and MoE: How These Techniques Slash LLM Serving Costs
Dec, 20 2025
Streaming Responses in LLM APIs: Architecture and User Experience
Oct, 30 2026
Measuring Generative AI Adoption: Telemetry, Surveys, and ROI
Sep, 6 2026