
Tag: distributed storage
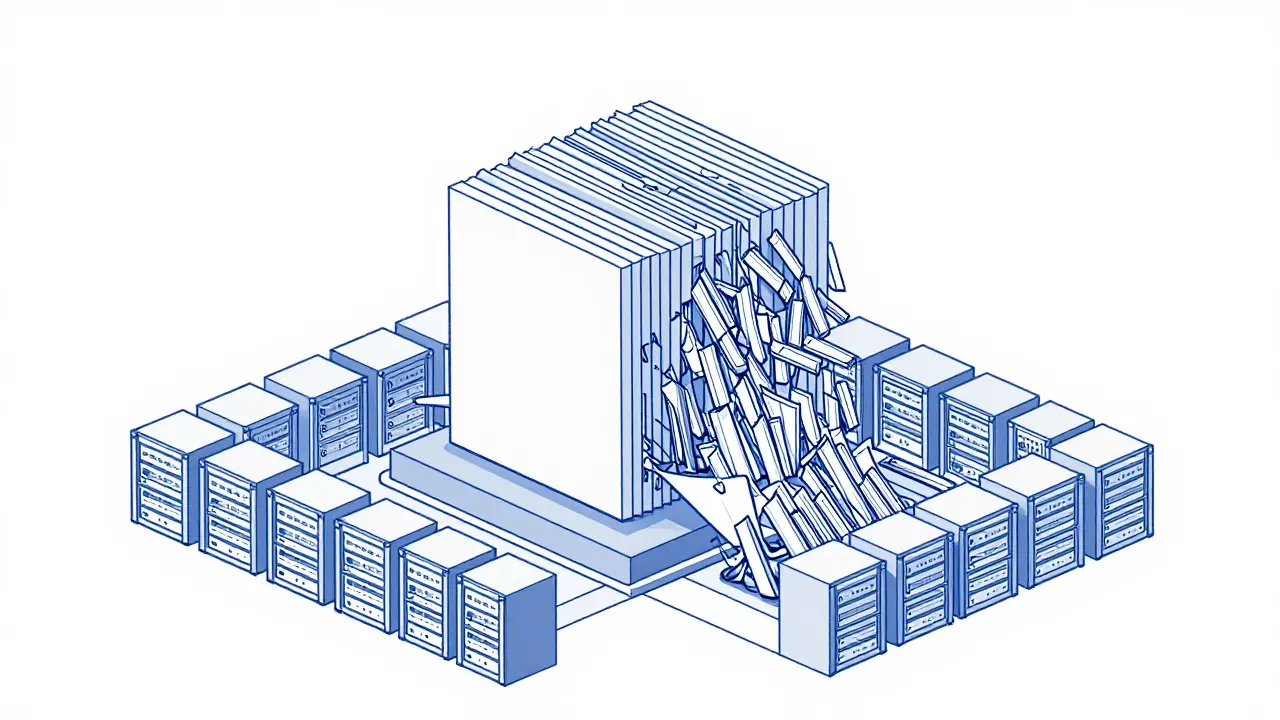
Learn how to optimize sharding and data loading for petabyte-scale LLM datasets. Discover tiered storage strategies, sharded data parallelism, and tips to prevent GPU idling in large-scale training pipelines.
Categories
 Artificial Intelligence
Archives
Recent-posts
Bias in Large Language Models: Sources, Measurement, and Mitigation
Mar, 18 2026
How Next-Gen LLMs Actually Follow Instructions: From RLHF to AutoIF
May, 16 2026
Measuring Generative AI Adoption: Telemetry, Surveys, and ROI
Sep, 6 2026
Safety and Harms Evaluation for Large Language Models in Production
Oct, 3 2026
Why Transformers Replaced RNNs: Parallelization and Long-Range Dependencies in LLMs
May, 4 2026