
Tag: GPU throughput
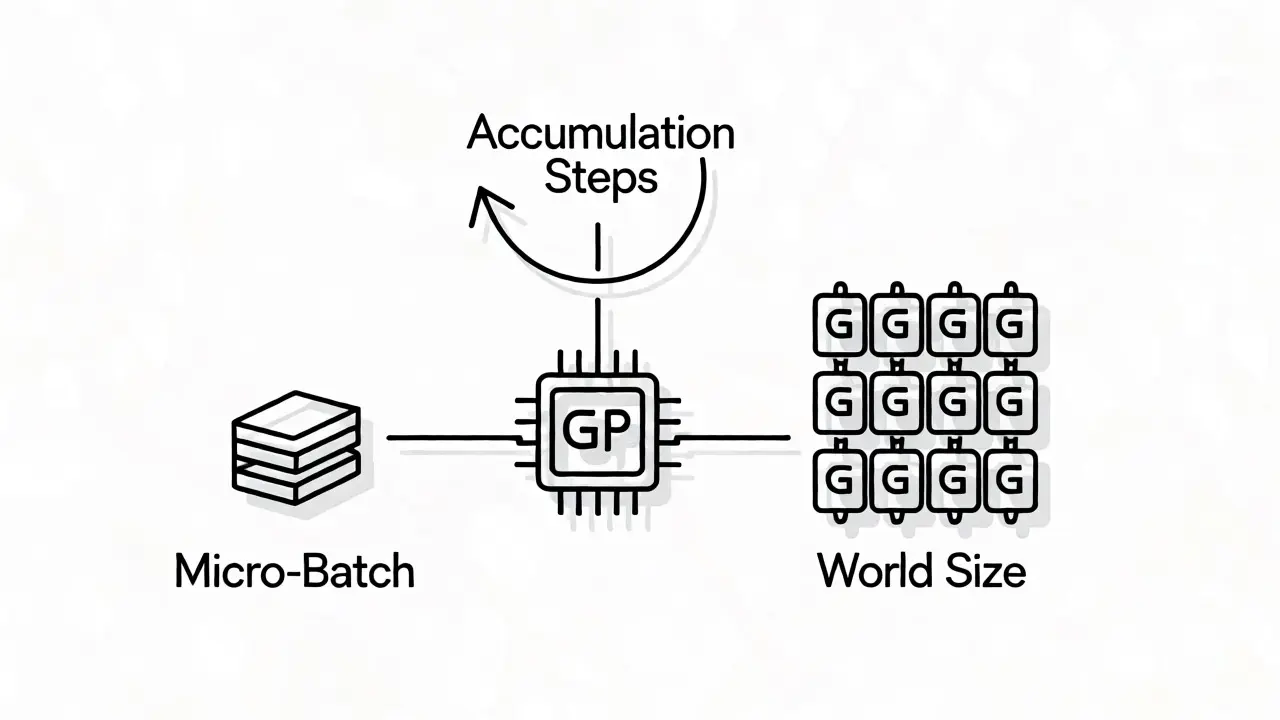
Learn how batch size, gradient accumulation, and throughput interact in LLM training. Discover practical tuning strategies for DeepSpeed and Megatron-LM to maximize GPU efficiency and reduce costs.
Categories
 Artificial Intelligence
Archives
Recent-posts
Incident Response for AI Defects: A Practical Guide
Aug, 30 2026
Adapter Layers and LoRA: Efficient LLM Customization Guide
Aug, 31 2026
Tokenization Strategies for LLMs: BPE, WordPiece, and Unigram Explained
Nov, 14 2026
How Non-Developers Use Vibe Coding to Launch Real Applications in 2026
Jul, 13 2026
Compressed LLM Evaluation: Essential Protocols for 2026
Feb, 5 2026