
Tag: gradient accumulation
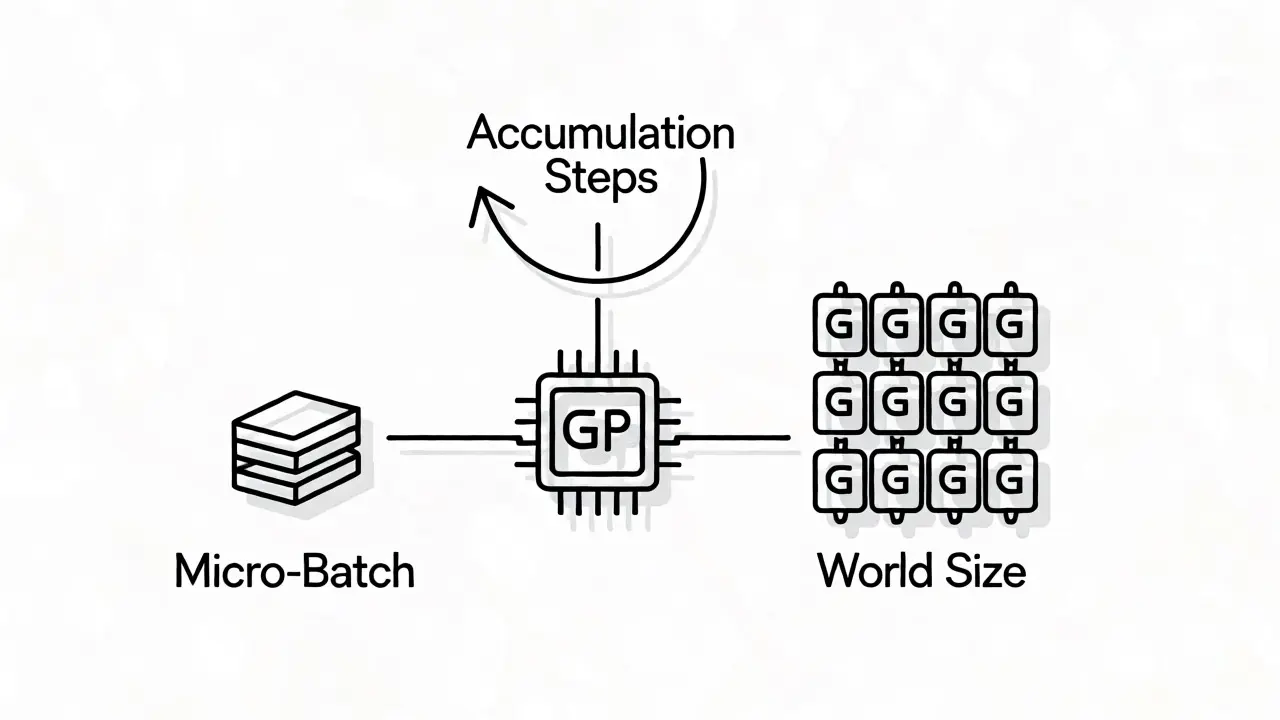
Learn how batch size, gradient accumulation, and throughput interact in LLM training. Discover practical tuning strategies for DeepSpeed and Megatron-LM to maximize GPU efficiency and reduce costs.
Categories
 Artificial Intelligence
Archives
Recent-posts
Federated Learning for LLMs: Training AI Without Centralizing Data
Apr, 9 2026
Enterprise Data Governance for LLM Deployments: A Practical Guide
Jun, 20 2026
Fine-Tuning Multimodal AI: Dataset Design, Alignment Losses, and PEFT Strategies
Jun, 24 2026
Hybrid Search for RAG: Combining Semantic and Keyword Retrieval
Jul, 26 2026

Guardrails Against Fabricated Citations in Generative AI
Sep, 9 2026