
Tag: KV caching LLM
Learn how streaming, batching, and caching reduce LLM response times. Real-world techniques used by AWS, NVIDIA, and vLLM to cut latency under 200ms while saving costs and boosting user engagement.
Categories
 Artificial Intelligence
Archives
Recent-posts
Practical Applications of Generative AI: A 2026 Industry Guide
Mar, 30 2026
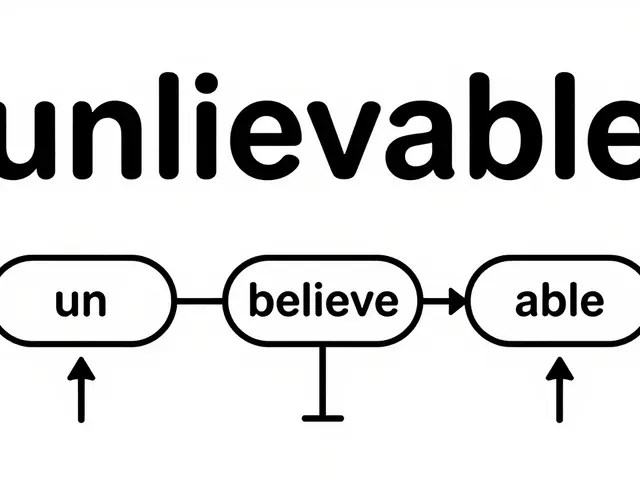
Transformer Architecture Explained: How LLMs Process Language
Jul, 12 2026
Confidential Computing for LLM Inference: Securing Data and Models with TEEs
Oct, 28 2026
Change Management for Generative AI: Adoption, Training, and Governance
Sep, 25 2026
Interoperability Patterns to Abstract Large Language Model Providers
Jul, 22 2025