
Tag: language model fairness
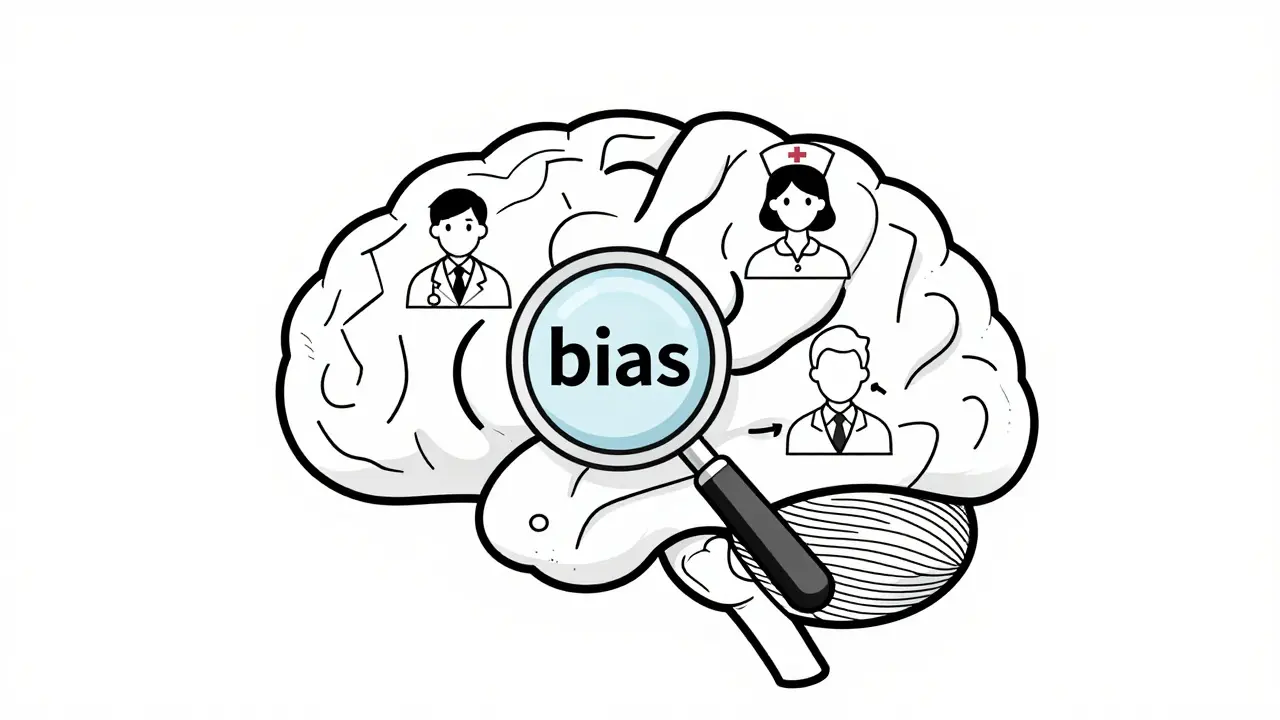
Large language models exhibit hidden biases from training data, human feedback, and internal architecture. New research reveals pro-AI bias, AI-AI bias, and methods to detect and fix them before they cause real harm.
Categories
 Artificial Intelligence
Archives
Recent-posts
Colorado SB24-205 Guide: AI Impact Assessments and Risk Management
Apr, 16 2026
Documentation First: Why AI Output Is Just a Draft
Sep, 18 2026
Schema-Constrained Prompts: Forcing JSON and Structured Outputs from LLMs
May, 25 2026
Tiered Governance for Vibe-Coded Apps: Matching Controls to Risk
Mar, 21 2026
Backlog Hygiene for Vibe Coding: How to Manage Defects, Debt, and Enhancements
Jan, 31 2026