
Tag: LLM benchmarking
Compare Transformer variants like GPT-4, BERT, and Nemotron-4. Learn how to benchmark LLM architectures for speed, accuracy, and cost in real-world workloads.
Categories
 Artificial Intelligence
Archives
Recent-posts
How to Stop AI Hallucinations: A Guide to Constraints, Quotes, and Extractive Prompting
Jun, 29 2026
Speculative Decoding Guide: Speed Up LLM Inference with Draft and Verifier Models
Apr, 25 2026
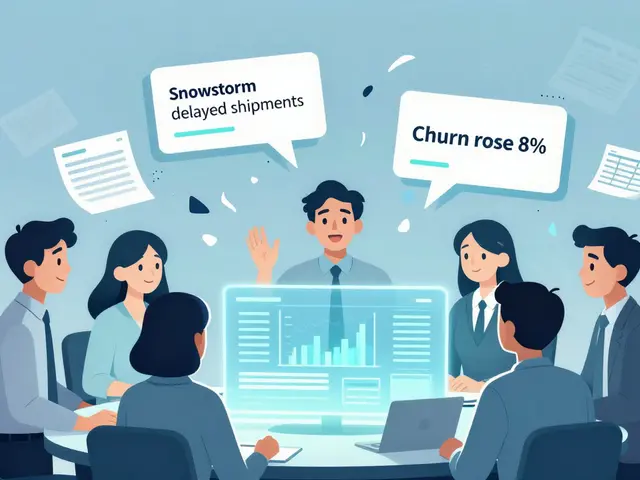
How Finance Teams Use Generative AI for Smarter Forecasting and Variance Analysis
Dec, 18 2025
Compression Impact on Multilingual and Domain-Specific Large Language Models
Jul, 23 2026
Prompt Sensitivity in Large Language Models: Why Small Word Changes Change Everything
Oct, 12 2025