
Tag: Mixtral-8x7B
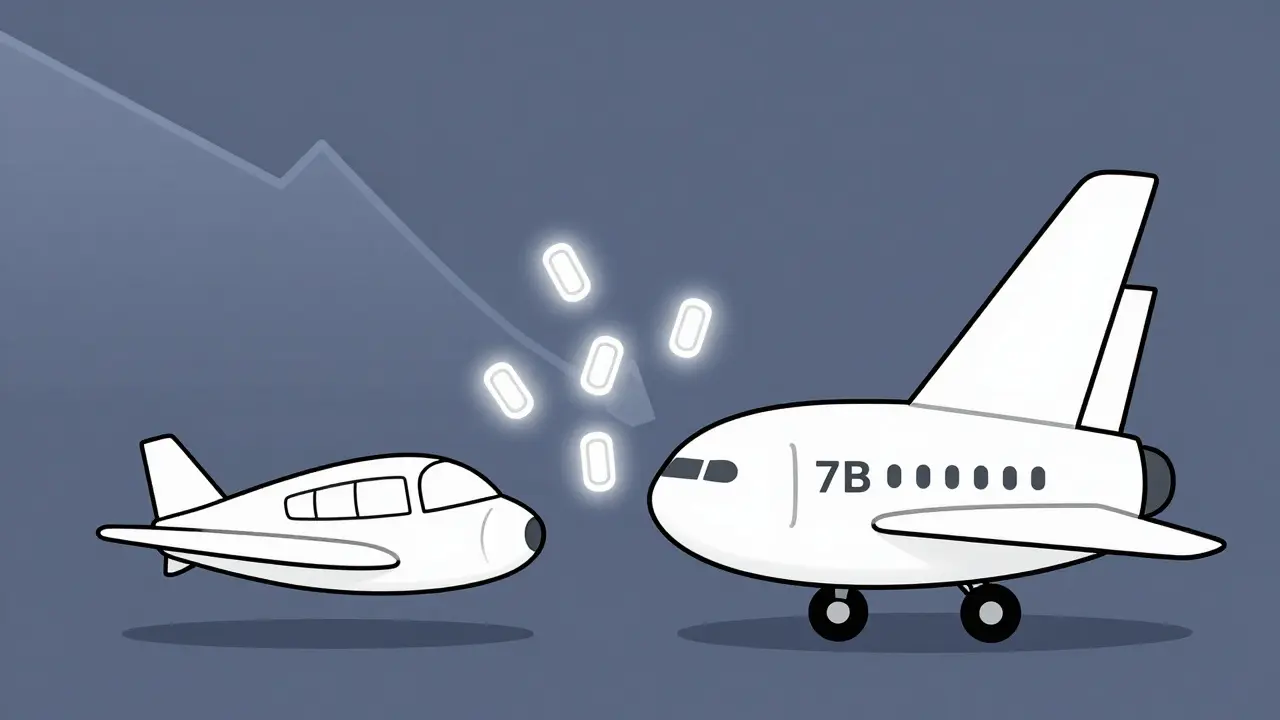
Speculative decoding and Mixture-of-Experts (MoE) are cutting LLM serving costs by up to 70%. Learn how these techniques boost speed, reduce hardware needs, and make powerful AI models affordable at scale.
Categories
 Artificial Intelligence
Archives
Recent-posts
Generative AI Interoperability: The Rise of MCP, APIs, and LLMOps Standards
Sep, 10 2026
How to Set Performance Budgets and Accessibility Rules in AI Prompts
May, 21 2026
Productivity Baselines Before Generative AI: Designing Fair Comparisons
Jun, 4 2026
Encoder-Decoder vs Decoder-Only Transformers: Choosing the Right Architecture for Your LLM
Jul, 18 2026
Transformer Architecture Explained: How LLMs Process Language
Jul, 12 2026