
Tag: neural network depth
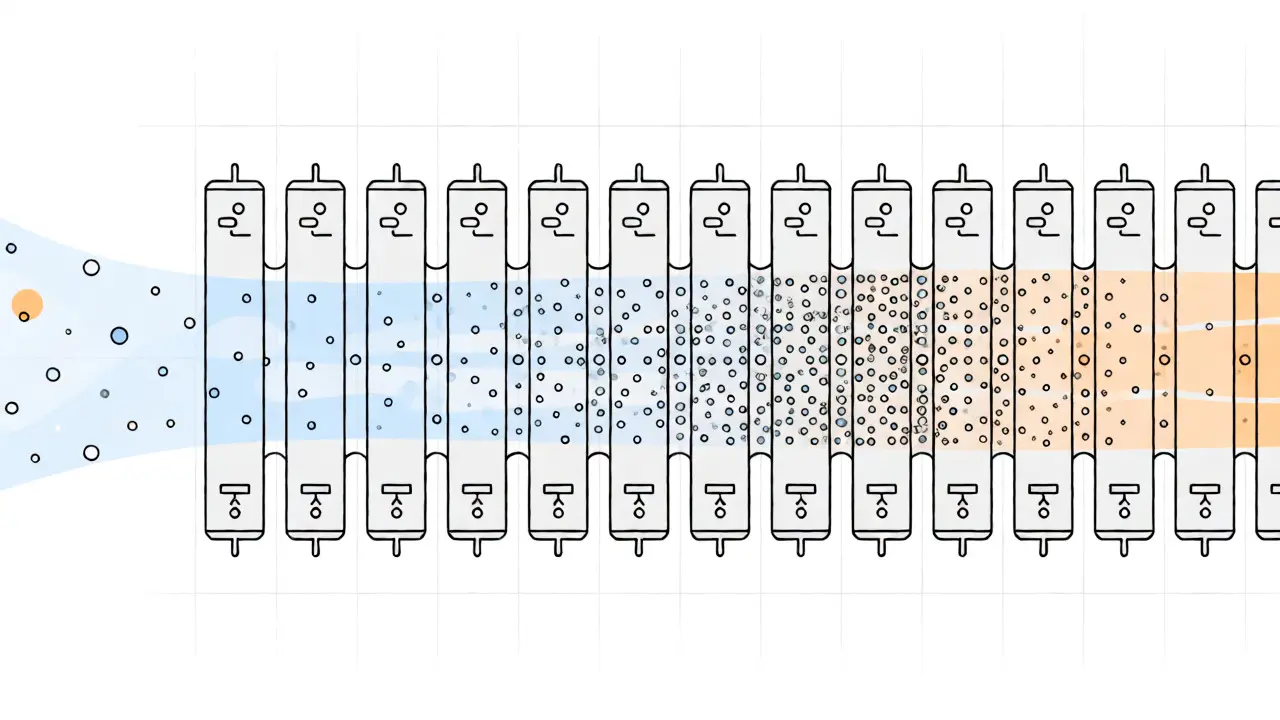
Discover why LLMs stack identical transformer blocks. Learn how depth builds hierarchical abstractions from syntax to reasoning, and why repetition ensures trainability.
Categories
 Artificial Intelligence
Archives
Recent-posts
Prompt Robustness: How to Make Large Language Models Handle Messy Inputs Reliably
Feb, 7 2026
How Training Duration and Token Counts Affect LLM Generalization
Dec, 17 2025
Hyperparameter Selection for Fine-Tuning Large Language Models Without Forgetting
Feb, 11 2026
Bias in Large Language Models: Sources, Measurement, and Mitigation
Mar, 18 2026
How Next-Gen LLMs Actually Follow Instructions: From RLHF to AutoIF
May, 16 2026