
Tag: on-prem AI
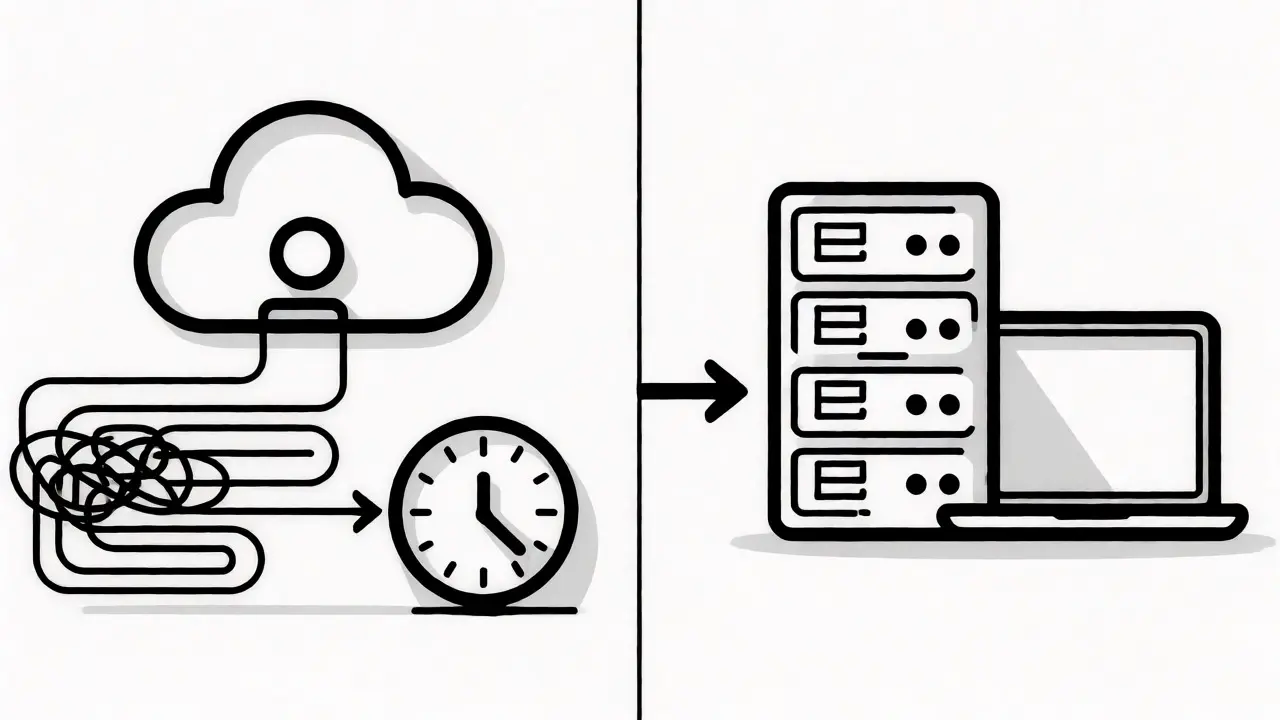
Deciding between API-based LLMs and on-prem deployment? We break down latency, control, and hidden costs to help you choose the right architecture for your AI projects.
Categories
 Artificial Intelligence
Archives
Recent-posts
Fine-Tuned Models for Niche Stacks: When Specialization Beats General LLMs
Jul, 5 2025
How to Choose the Right Vibe Coding Platform for Your Team in 2026
May, 18 2026
Navigating the Generative AI Landscape: Practical Strategies for Leaders
Feb, 17 2026
Curriculum and Data Mixtures: Accelerating LLM Scaling in 2026
May, 31 2026
Runtime Protections for Vibe-Coded Services: WAFs, RASP, and Rate Limits
May, 28 2026