
Tag: RAG optimization
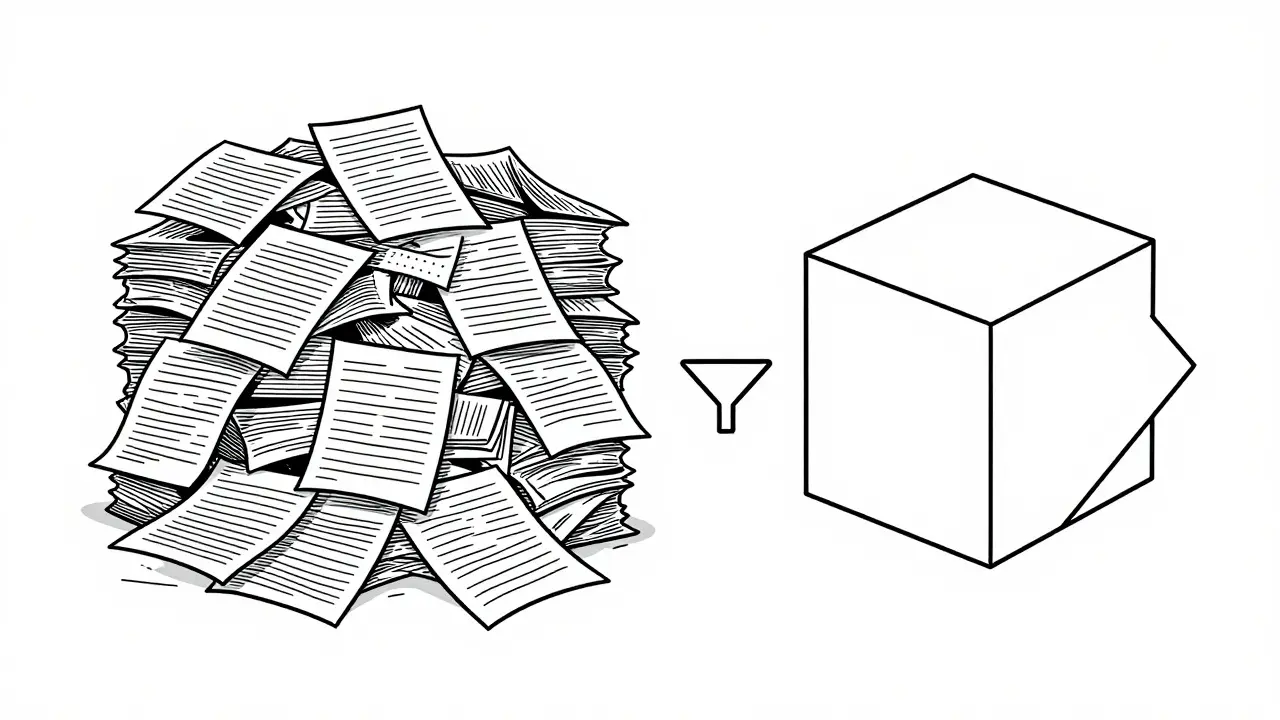
Learn how compression-aware prompting optimizes small LLMs by distilling prompts. Explore techniques like TPC and LJMLingua to cut costs, boost speed, and improve RAG accuracy.
Categories
 Artificial Intelligence
Archives
Recent-posts
Compression Impact on Multilingual and Domain-Specific Large Language Models
Jul, 23 2026
Safety Use Cases for Large Language Models in Regulated Industries
Jul, 8 2026
Attention Mechanisms in Generative AI: From Self-Attention to Flash Attention
Oct, 15 2026
AI Risk Registers for Generative AI: Documenting Systems and Controls
Oct, 2 2026
Few-Shot Prompting Guide: Boost AI Accuracy with Examples
Jul, 20 2026