
Tag: semantic caching
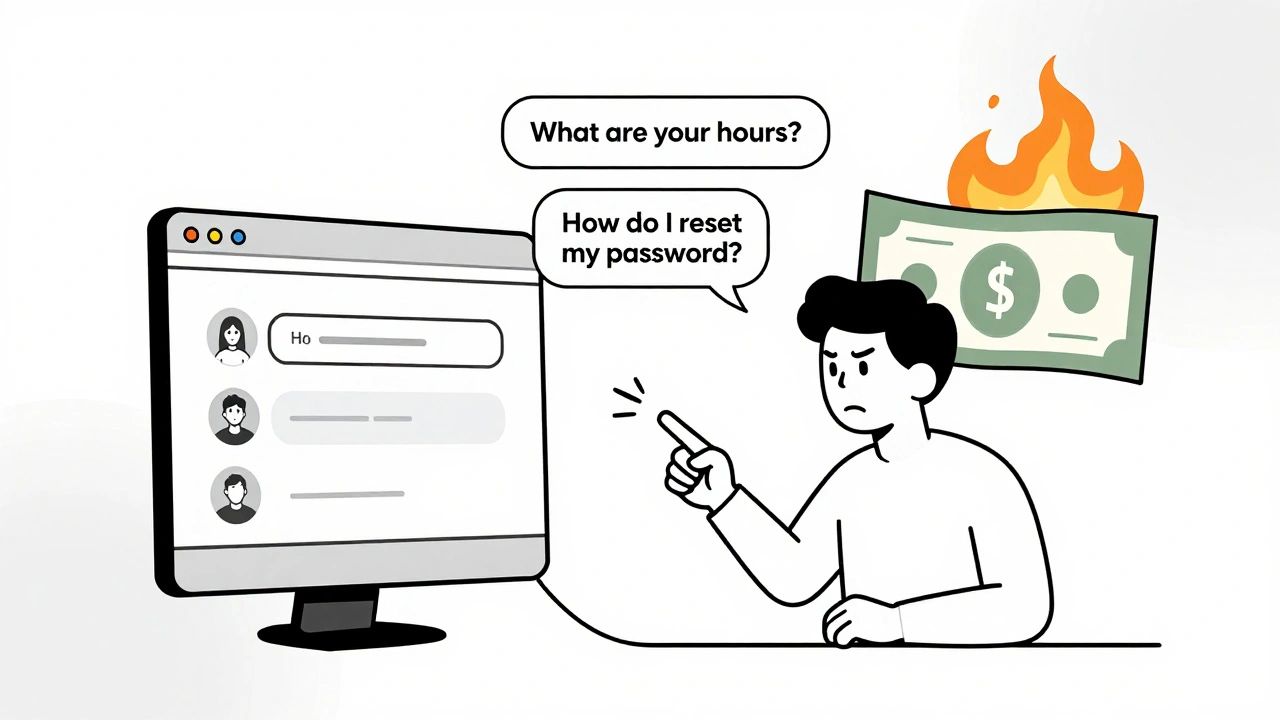
Caching is essential for AI web apps to reduce latency and cut costs. Learn how to start with prompt caching, semantic search, and Redis to make your AI responses faster and cheaper.
Categories
 Artificial Intelligence
Archives
Recent-posts

Guardrails Against Fabricated Citations in Generative AI
Sep, 9 2026
Disaster Recovery for Large Language Model Infrastructure: Backups and Failover
Dec, 7 2025
Prompting Strategies for Effective Vibe Coding: Best Practices & Guide
Aug, 16 2026
Adapter Layers and LoRA: Efficient LLM Customization Guide
Aug, 31 2026
Cost-Aware Scheduling for LLM Workloads: A Practical Guide to Saving Money and Meeting SLOs
Aug, 13 2026