
Tag: transformer efficiency
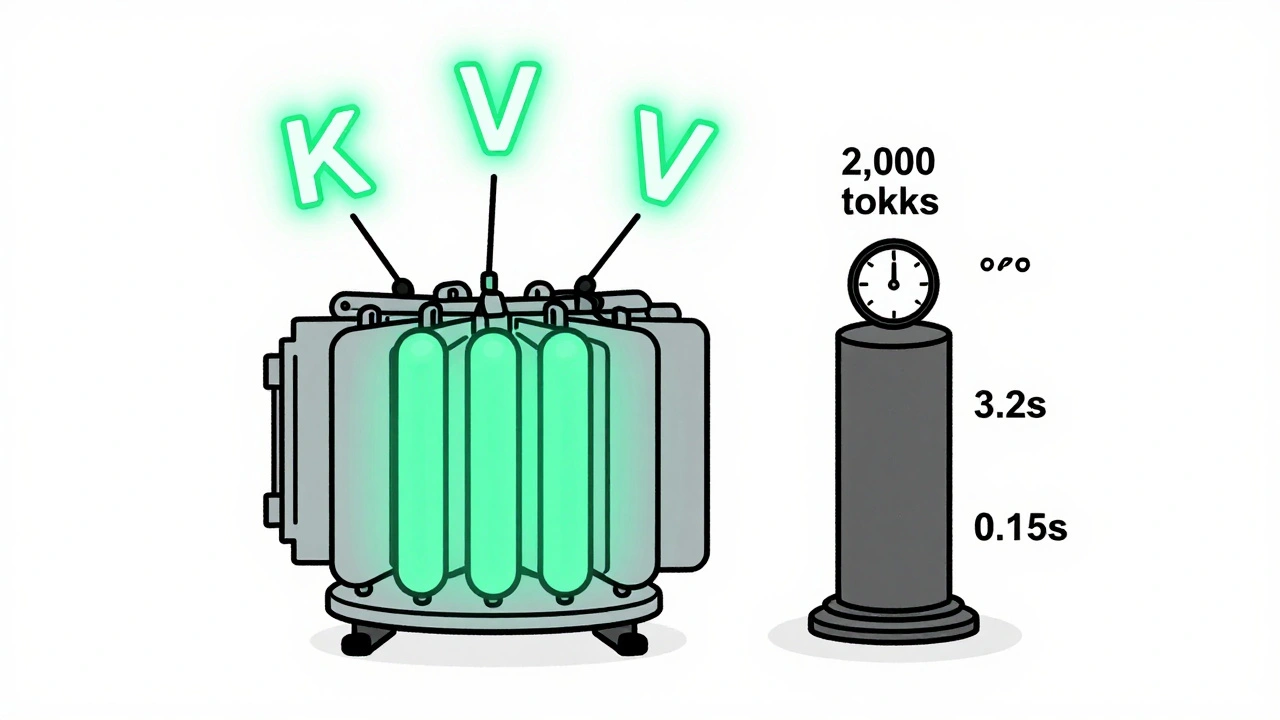
KV caching and continuous batching are essential for fast, affordable LLM serving. Learn how they reduce memory use, boost throughput, and enable real-world deployment on consumer hardware.
Categories
 Artificial Intelligence
Archives
Recent-posts
Enterprise Adoption, Governance, and Risk Management for Vibe Coding
Dec, 16 2025
Prompting Strategies for Effective Vibe Coding: Best Practices & Guide
Aug, 16 2026
Federated Learning for LLMs: Training AI Without Centralizing Data
Apr, 9 2026
How to Write Maintainable Prompts for Clean, Lasting Code
Jul, 17 2026
Vibe Coding Strategic Briefing: Balancing Rapid Prototyping with Enterprise Risk
Apr, 18 2026