
Tag: AI bias
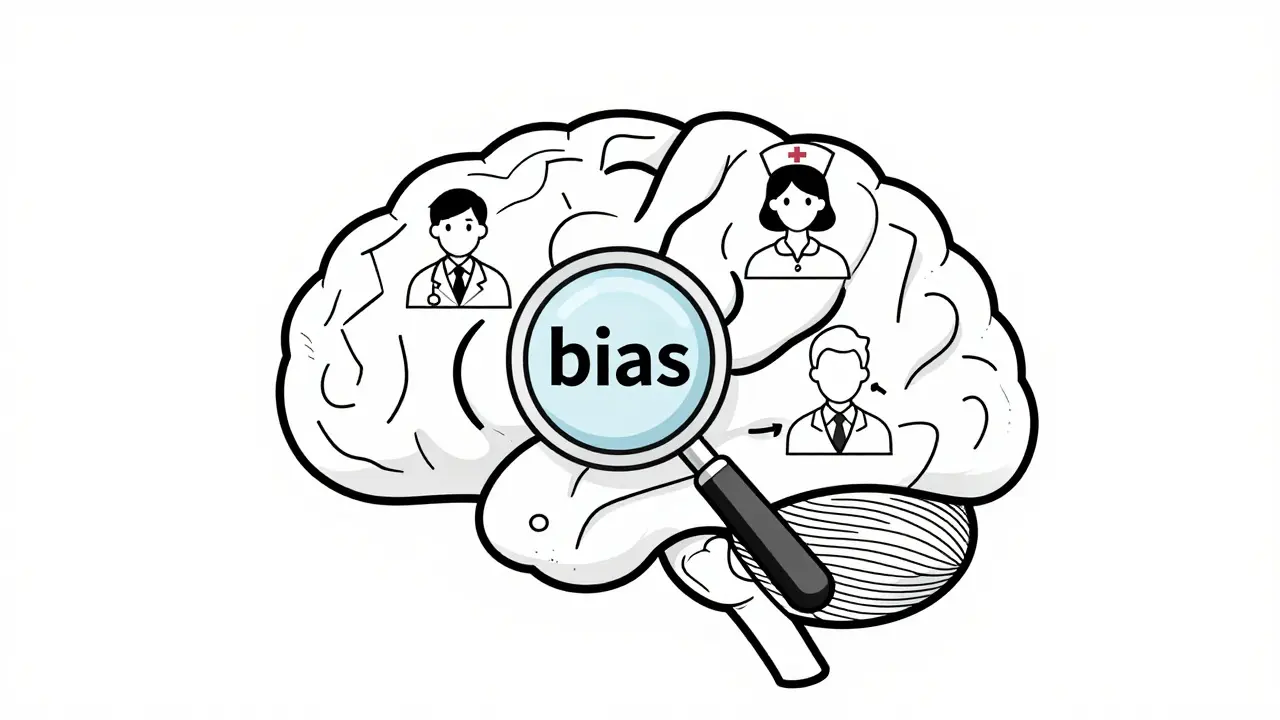
Large language models exhibit hidden biases from training data, human feedback, and internal architecture. New research reveals pro-AI bias, AI-AI bias, and methods to detect and fix them before they cause real harm.
Categories
 Artificial Intelligence
Archives
Recent-posts
Prompt Robustness: How to Make Large Language Models Handle Messy Inputs Reliably
Feb, 7 2026
Validation and Early Stopping for LLM Training: A Practical Guide
Oct, 25 2026
Few-Shot Prompting Guide: Boost AI Accuracy with Examples
Jul, 20 2026
NLP Research Trends Shaping the Next Generation of Large Language Models in 2026
May, 6 2026
Generative AI Interoperability: The Rise of MCP, APIs, and LLMOps Standards
Sep, 10 2026