
Tag: API latency
Discover how streaming responses in LLM APIs enhance user experience by delivering tokens incrementally. Learn about SSE architecture, provider differences, and frontend optimization techniques to build responsive AI applications.
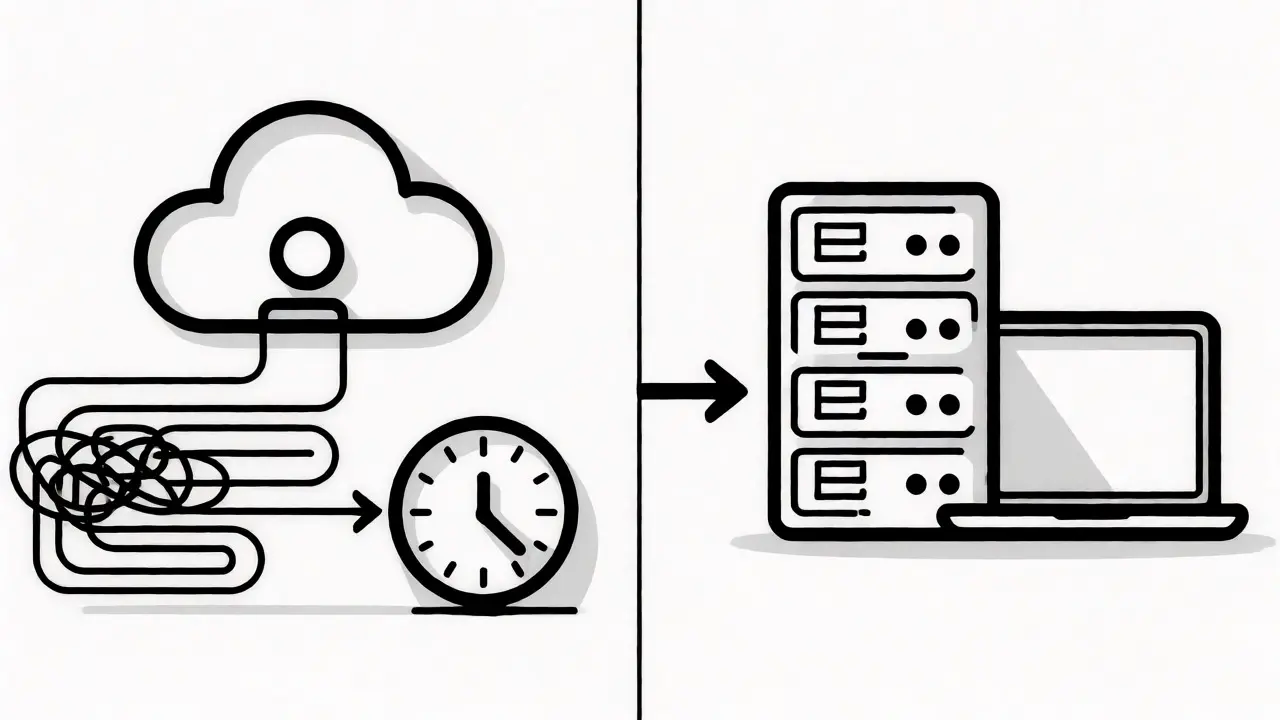
Deciding between API-based LLMs and on-prem deployment? We break down latency, control, and hidden costs to help you choose the right architecture for your AI projects.
Categories
 Artificial Intelligence
Archives
Recent-posts
Workflow Automation with LLM Agents: When Rules Meet Reasoning
Jun, 28 2026
Domain-Specialized Large Language Models: Code, Math, and Medicine
Oct, 3 2025
Understanding Per-Token Pricing for Large Language Model APIs: A Cost Guide
May, 2 2026
Navigating the Generative AI Landscape: Practical Strategies for Leaders
Feb, 17 2026
Scaling Open-Source LLMs: Hardware, Serving Stacks, and Playbooks for 2026
Apr, 13 2026