
Tag: LLM compression
Struggling with LLM costs or performance? Learn when to compress models via quantization versus switching to smaller architectures. Make smarter AI deployment decisions.
Explore how LLM compression affects multilingual support and domain accuracy. Learn why quantization hurts low-resource languages and increases bias in medical/legal AI.
Learn how to restore accuracy in compressed LLMs using local reconstruction, EoRA, and post-quantization fine-tuning. Avoid costly full retraining with these efficient recovery techniques.
Combining pruning and quantization cuts LLM inference time by up to 6x while preserving accuracy. Learn how HWPQ's unified approach with FP8 and 2:4 sparsity delivers real-world speedups without hardware changes.
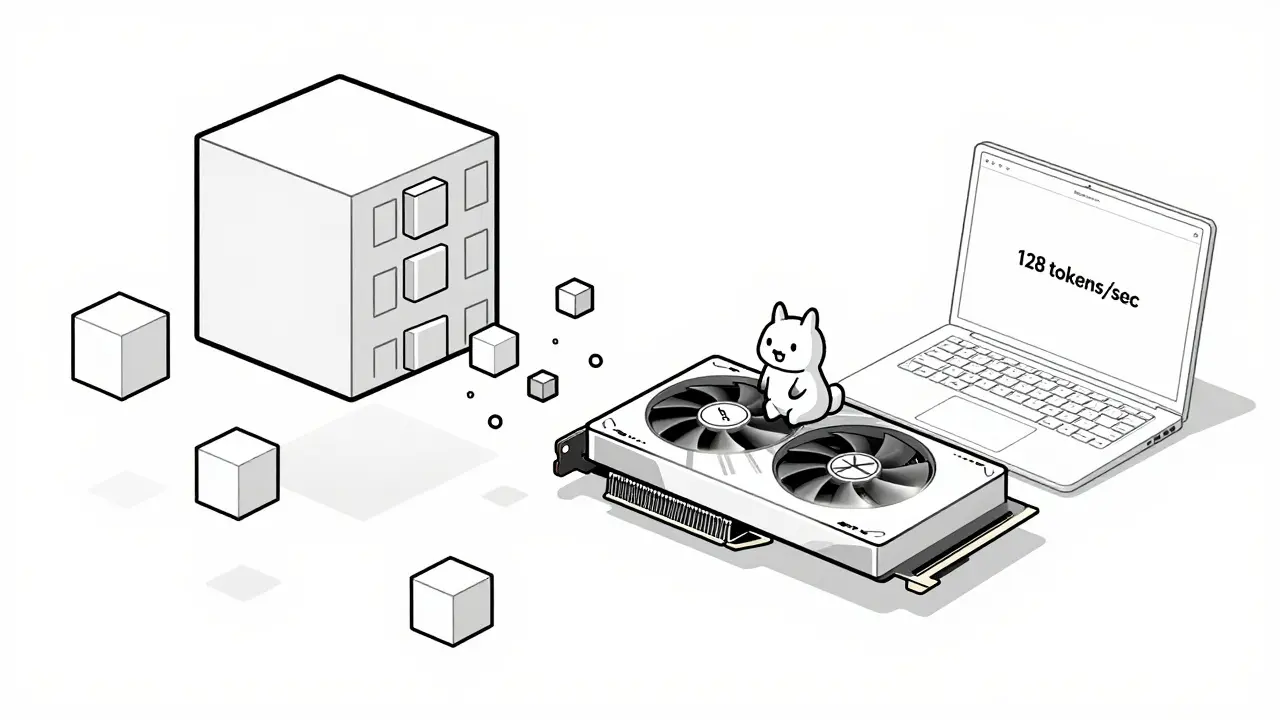
Learn how hardware-friendly LLM compression lets you run powerful AI models on consumer GPUs and CPUs. Discover quantization, sparsity, and real-world performance gains without needing a data center.
Categories
 Artificial Intelligence
Archives
Recent-posts
Accessibility Regulations for Generative AI Products: WCAG and Assistive Features
Mar, 6 2026
How to Measure Generative AI ROI: Solving Attribution Challenges in 2026
May, 17 2026
How Large Language Models Are Creating Personalized Learning Paths in Education
Feb, 14 2026
Design Systems for AI-Generated UI: Keeping Components Consistent
Mar, 11 2026
Scaling Multilingual LLMs: The Data Balance and Coverage Guide
Jun, 21 2026