
Tag: multi-GPU inference
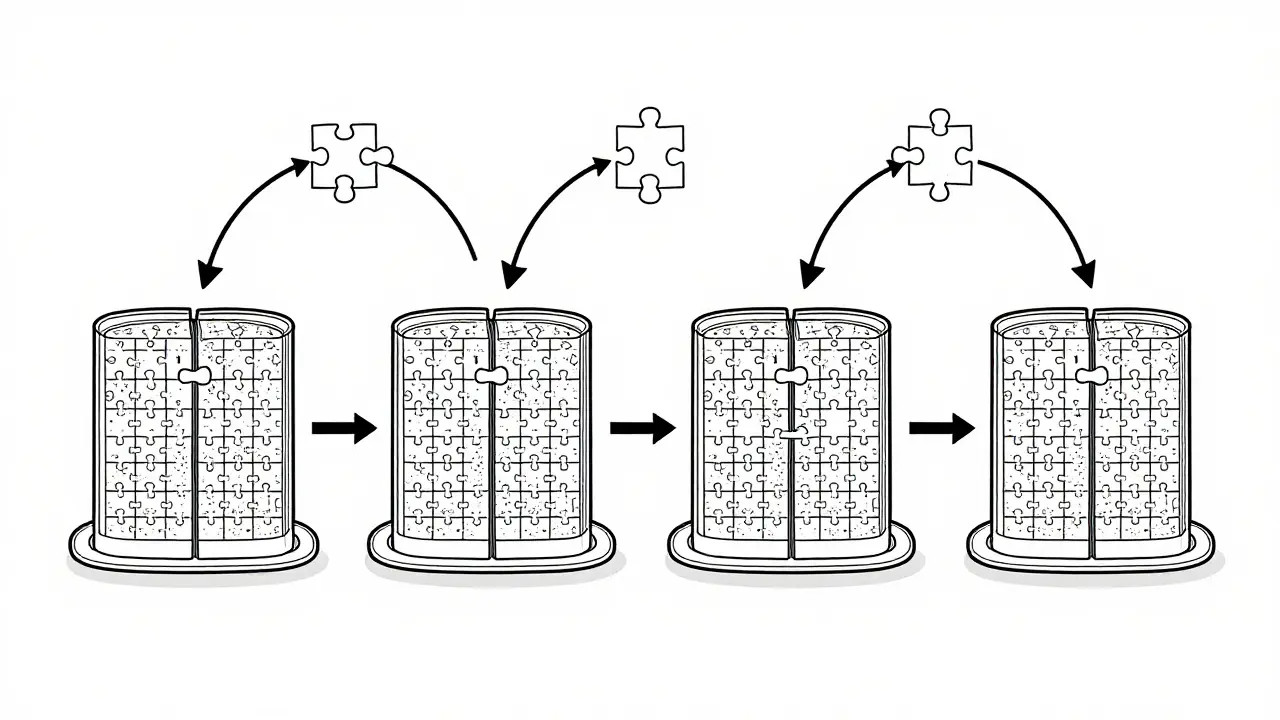
Tensor parallelism lets you run massive LLMs across multiple GPUs by splitting model layers. Learn how it works, why NVLink matters, which frameworks support it, and how to avoid common pitfalls in deployment.
Categories
 Artificial Intelligence
Archives
Recent-posts
Multimodal Evolution in Generative AI: 3D, Haptics, and Sensor Fusion
Sep, 28 2026
Evaluating Factuality During LLM Generation: Online Verification Strategies
Oct, 4 2026
Why Transformers Replaced RNNs: Parallelization and Long-Range Dependencies in LLMs
May, 4 2026
Hybrid Cloud vs On-Prem: Best Strategies for LLM Serving in 2026
Sep, 3 2026
Evaluation 2.0 for Generative AI: Moving Beyond Static Benchmarks to Live Tasks
Aug, 1 2026