
Tag: retrieval-augmented generation
Explore how combining RAG with decoding strategies like LoRAG and Layer Fused Decoding reduces LLM hallucinations and boosts factual accuracy in AI responses.
Choosing the right embedding model for your enterprise RAG pipeline isn't about benchmarks - it's about speed, security, and domain-specific accuracy. Learn what actually works in production and how to avoid costly mistakes.
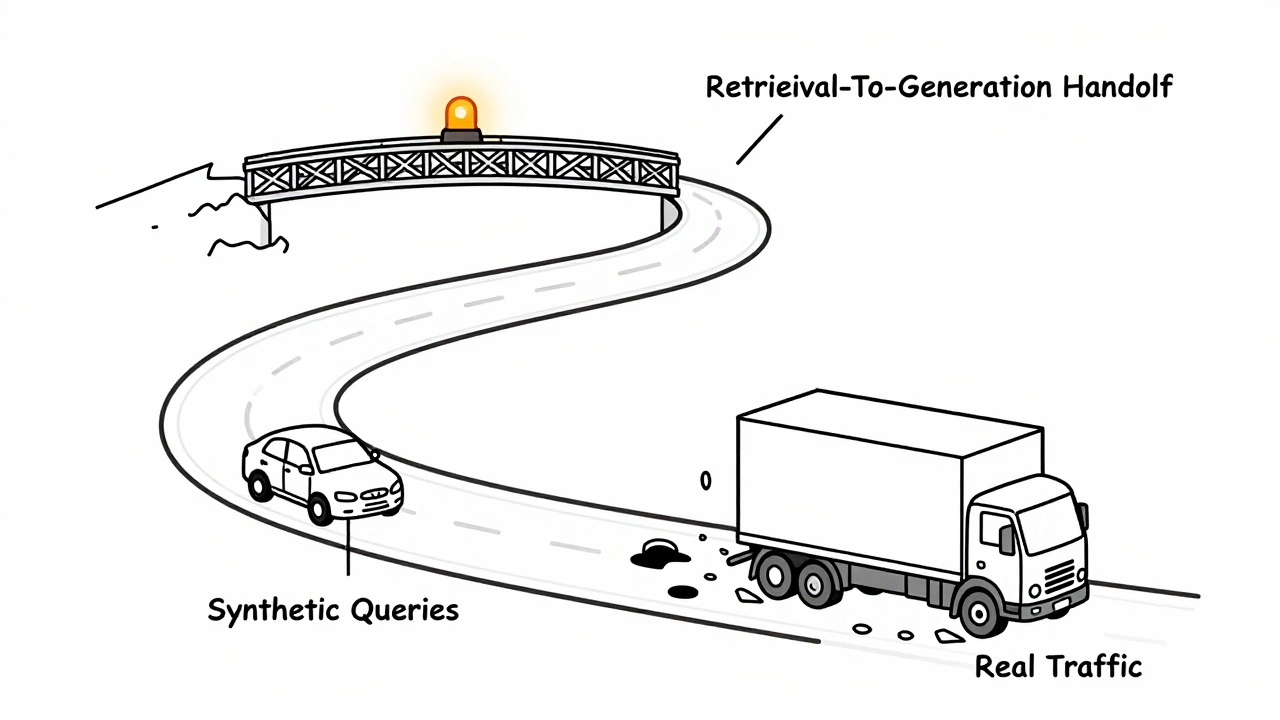
Testing RAG pipelines requires both synthetic queries and real traffic monitoring. Learn how to measure retrieval, generation, cost, and latency-and turn production failures into better tests.
Categories
 Artificial Intelligence
Archives
Recent-posts
Pattern Libraries for AI: How Reusable Templates Improve Vibe Coding
Jan, 8 2026
Legal Review Steps for Vibe-Coded Features Touching Customer Data
Sep, 30 2026
Why Tokenization Still Matters in the Age of Large Language Models
Sep, 21 2025
State Management Choices in AI-Generated Frontends: Pitfalls and Fixes
Mar, 12 2026
Logging and Observability for Production LLM Agents: A Complete Guide
Apr, 24 2026