
Tag: AI efficiency
Struggling with LLM costs or performance? Learn when to compress models via quantization versus switching to smaller architectures. Make smarter AI deployment decisions.
Explore how Mixture-of-Experts (MoE) architectures cut AI costs by up to 16x while managing memory and quality tradeoffs. Learn when to use MoE vs. Dense models.
Categories
 Artificial Intelligence
Archives
Recent-posts
Why Understanding Every Line of AI-Generated Code Isn't the Goal in Vibe Coding
Mar, 27 2026

How Generative AI Is Transforming Prior Authorization Letters and Clinical Summaries in Healthcare Admin
Dec, 15 2025
Designing Multimodal Generative AI Apps: Input Strategies and Output Formats
Aug, 23 2026
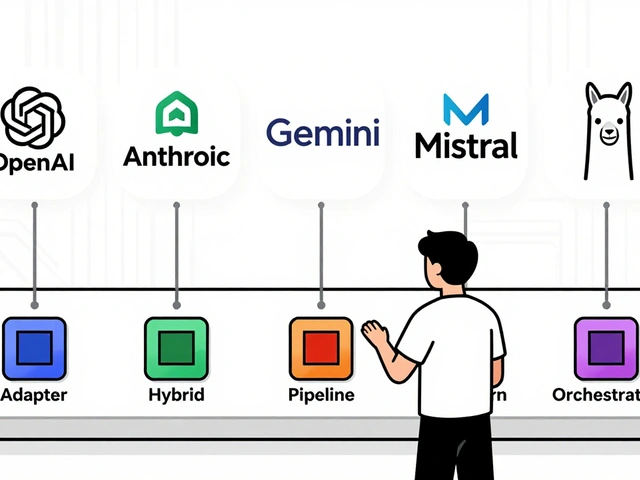
Interoperability Patterns to Abstract Large Language Model Providers
Jul, 22 2025
Prompt Robustness: How to Make Large Language Models Handle Messy Inputs Reliably
Feb, 7 2026