
Tag: LLM fine-tuning
Learn why LLMs lose general skills after fine-tuning and how to fix it. Discover how LoRA and PEFT preserve benchmark transfer, preventing catastrophic forgetting.
Discover how LoRA and Adapter Layers revolutionize LLM customization. Learn when to use each for efficient fine-tuning, lower costs, and faster inference.
Struggling to choose between instruction tuning and task-specific fine-tuning? Learn the key differences, costs, and when to use each strategy for your LLM project.
Explore proven techniques to prevent catastrophic forgetting in LLM fine-tuning. We analyze LoRA, EWC, FIP, and hybrid methods to help you preserve model knowledge.
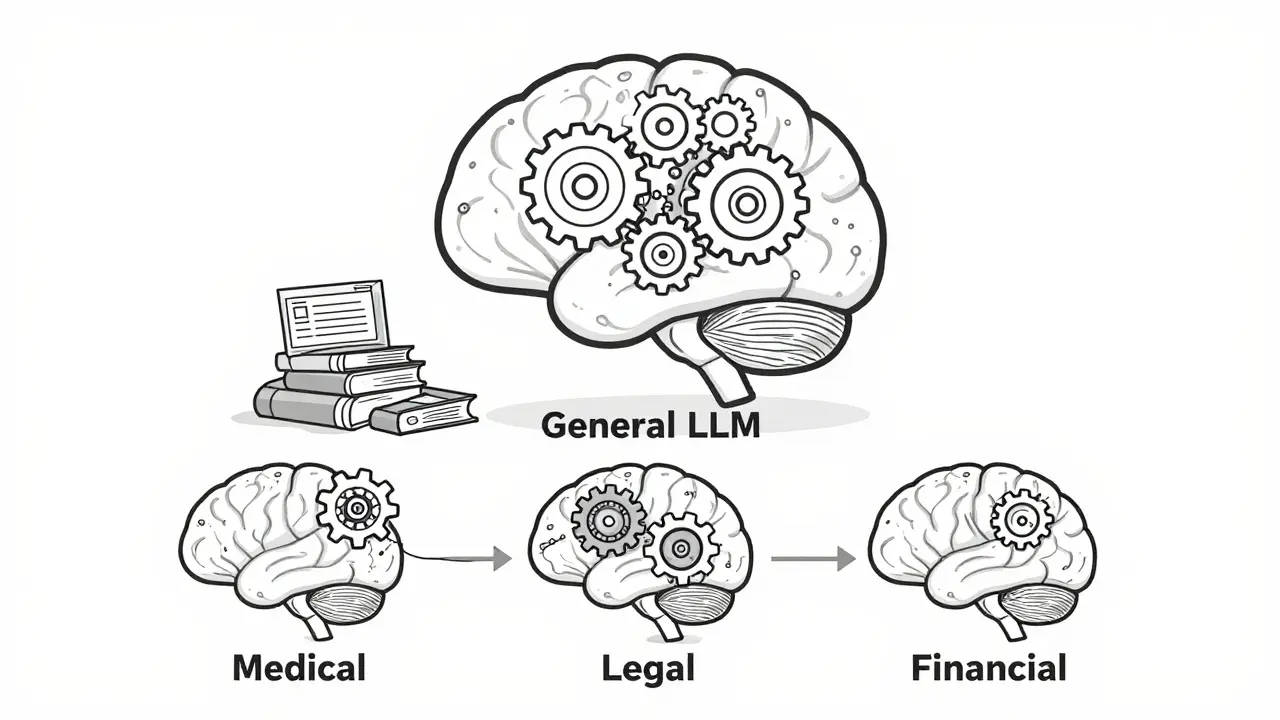
Domain adaptation in NLP lets you fine-tune large language models to understand specialized fields like medicine, law, or finance. Learn how it works, what methods deliver the best results, and why it's essential for real-world AI applications.
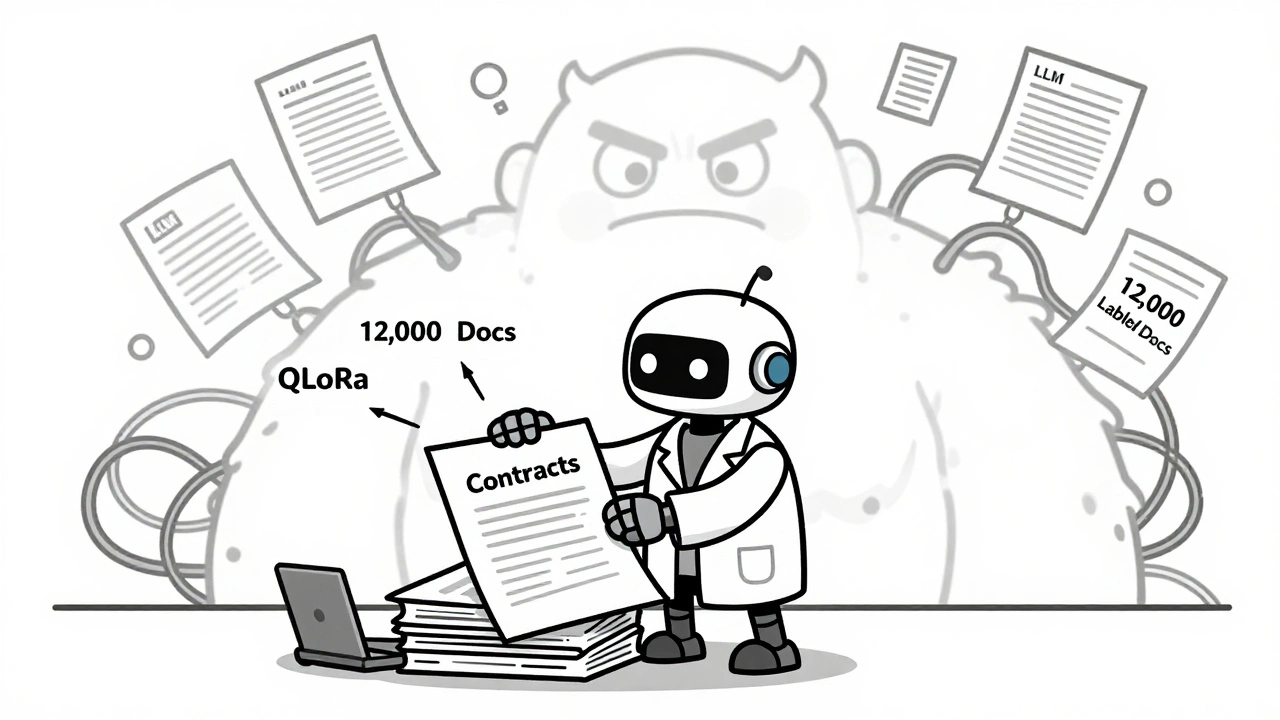
Fine-tuned LLMs outperform general models in niche tasks like legal analysis, medical coding, and compliance. Learn how specialization beats scale, when to use QLoRA, and why hybrid RAG systems are the future.
Categories
 Artificial Intelligence
Archives
Recent-posts
How to Measure Generative AI ROI: Solving Attribution Challenges in 2026
May, 17 2026
GDPR for Vibe Coders: Data Minimization & Consent Flows
Sep, 19 2026
Preventing Catastrophic Forgetting During LLM Fine-Tuning: Techniques That Work
Apr, 1 2026
Vibe Coding Talent Markets: Which Skills Actually Get You Hired in 2026
Apr, 23 2026
Documentation First: Why AI Output Is Just a Draft
Sep, 18 2026