
Tag: self-attention
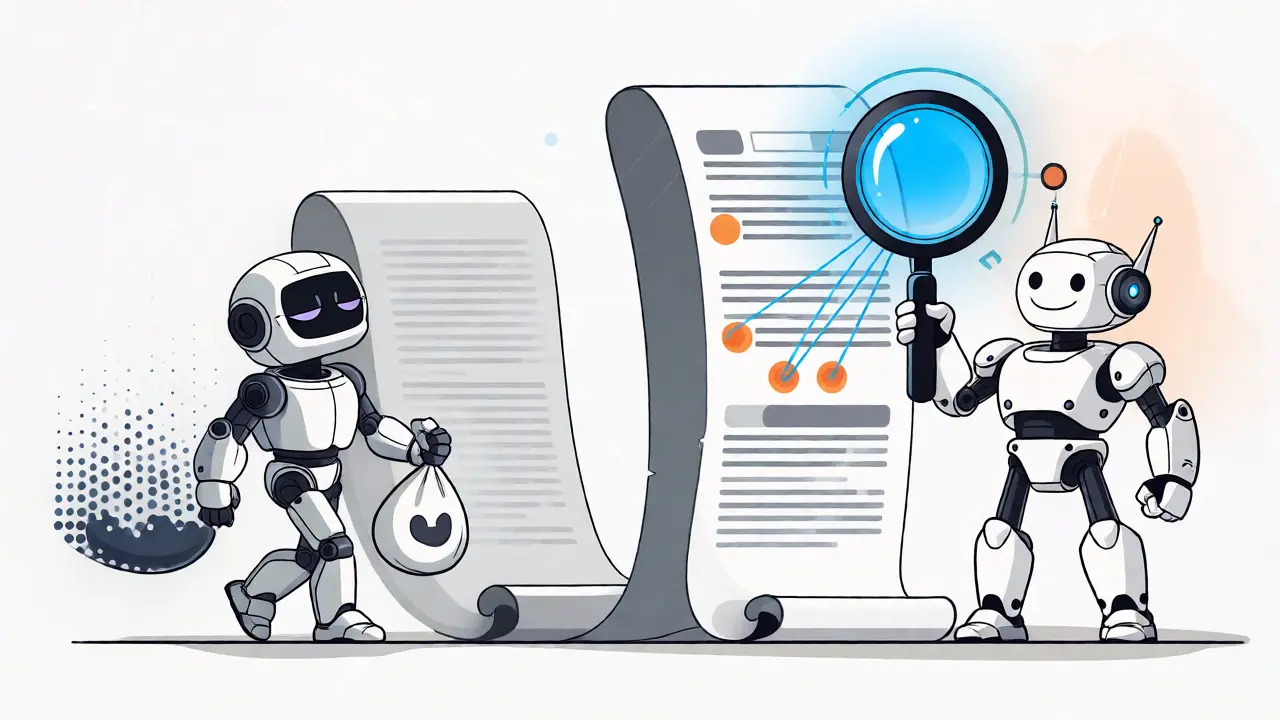
Explore how attention mechanisms evolved from simple alignment weights to Flash Attention. Learn why self-attention powers modern LLMs and how IO-aware optimizations solve memory bottlenecks.
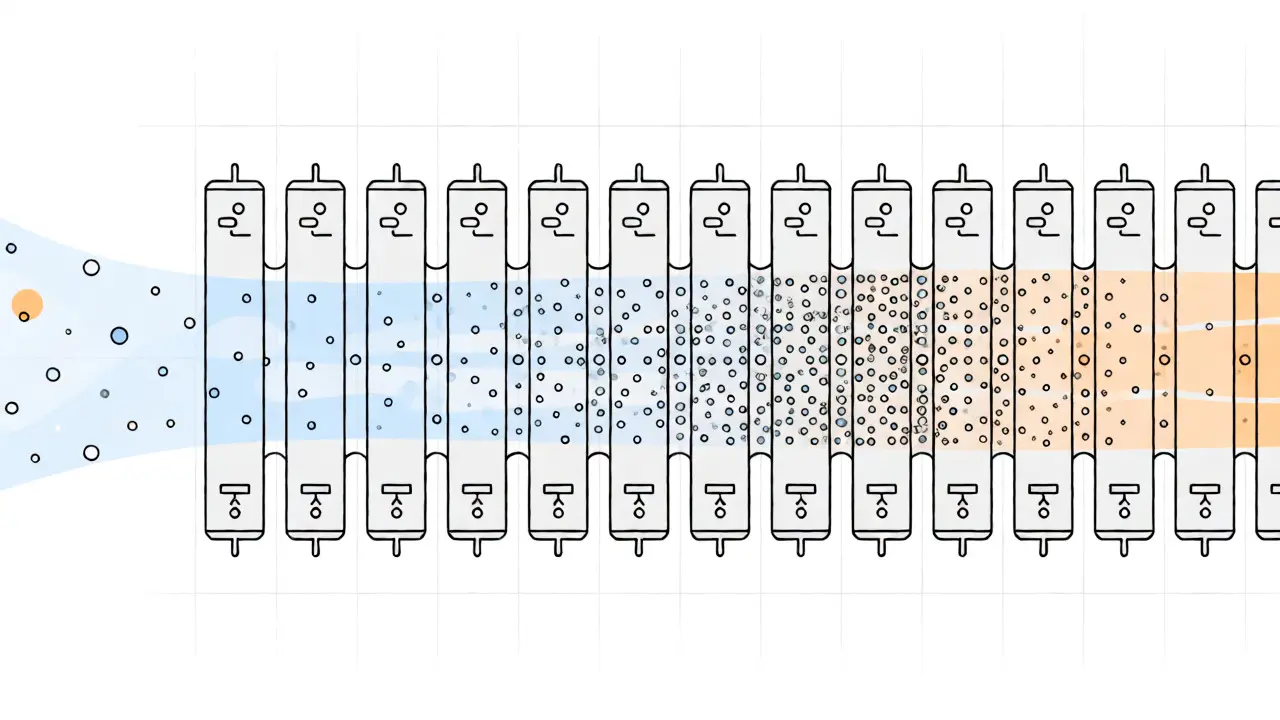
Discover why LLMs stack identical transformer blocks. Learn how depth builds hierarchical abstractions from syntax to reasoning, and why repetition ensures trainability.
Categories
 Artificial Intelligence
Archives
Recent-posts
Team Size Compression: How to Deliver More with Smaller, Leaner Teams
May, 8 2026
Long-Context AI Explained: Rotary Embeddings, ALiBi & Memory Mechanisms
Feb, 4 2026
Design Tokens and Theming in AI-Generated UI Systems
Feb, 13 2026
Model Selection for Vibe Coding: Claude, GPT-4, and Gemini Compared
Aug, 9 2026
Enterprise Adoption, Governance, and Risk Management for Vibe Coding
Dec, 16 2025