
Author: Phillip Ramos - Page 14
A comprehensive guide to Colorado SB24-205. Learn how to handle AI impact assessments, risk management for high-risk systems, and compliance for Generative AI.
Master the art of prompt libraries for Generative AI. Learn the essentials of governance, version control, and best practices to scale AI output and maintain quality.
Learn how to scale open-source LLMs in 2026. Explore hardware needs for gpt-oss-120b, the role of SLMs, and professional serving stacks using vLLM and SGLang.
Learn how to identify and mitigate AI hallucinations. Explore practical strategies like RAG, RLHF, and prompt engineering to ensure your generative AI outputs are reliable.
Learn how to detect and fix model drift after fine-tuning LLMs. Guide on JS divergence, concept drift, and monitoring tools to maintain model stability.
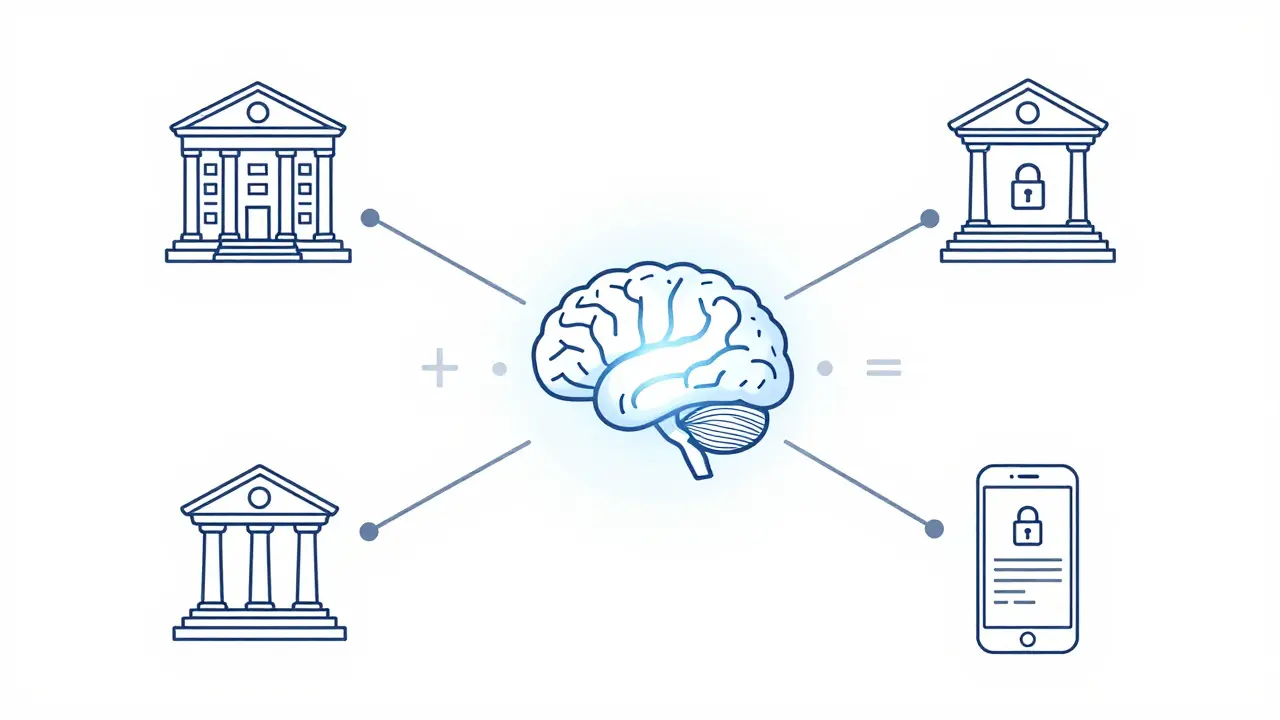
Learn how Federated Learning enables training Large Language Models (LLMs) without centralizing sensitive data, ensuring privacy and regulatory compliance.
Learn how to integrate vibe coding into enterprise projects. Discover strategies for setting expectations, using PLAN.md, and balancing AI speed with senior oversight.
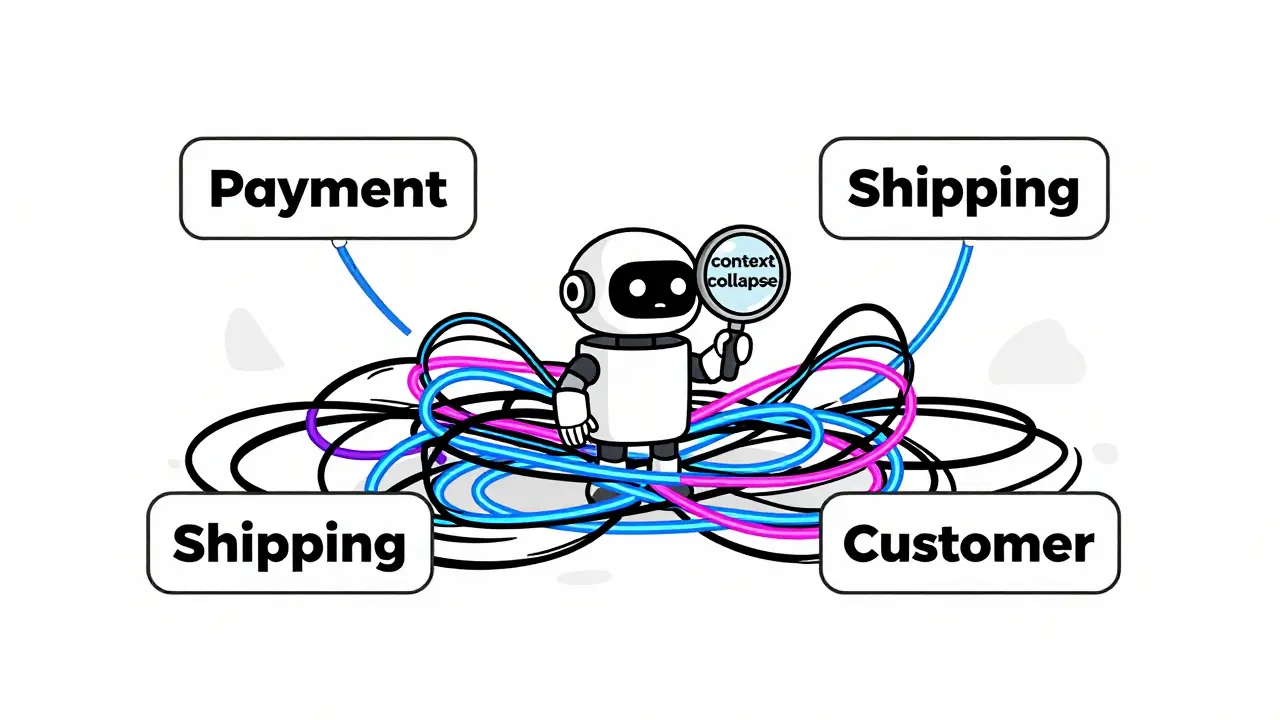
Learn how to combine Domain-Driven Design (DDD) with Vibe Coding to build scalable AI-assisted systems without falling into the trap of context collapse.
Explore how tokenizer design choices, vocabulary size, and algorithms like BPE and Unigram impact LLM accuracy, memory usage, and numerical reasoning.
Compare vLLM and TGI for LLM serving. Learn about PagedAttention, throughput benchmarks, and which framework fits your API's latency and scale needs.
Compare Transformer variants like GPT-4, BERT, and Nemotron-4. Learn how to benchmark LLM architectures for speed, accuracy, and cost in real-world workloads.
Explore when to use Edge Inference and Small Language Models (SLMs) over the cloud. Learn about model compression, latency, and on-device AI trade-offs.
Categories
 Artificial Intelligence
Archives
Recent-posts
LLM Compression vs. Model Switching: A Decision Guide for 2026
Sep, 16 2026
Service Level Objectives for Maintainability: Key Indicators and How to Set Alerts
Mar, 16 2026
Compression-Aware Prompting: Getting the Best from Small LLMs
Jun, 7 2026
Compression Impact on Multilingual and Domain-Specific Large Language Models
Jul, 23 2026
Guarded Tool Access: Sandboxing External Actions in LLM Agents
Mar, 2 2026